One Query Hung for 54 Minutes, Causing Sitewide 504s via MyISAM Locks

Every page returned 504 at once. Most people would suspect exhausted RAM or a full disk, but this time the cause was a single unattended SELECT stuck on a thirty-megabyte MyISAM table.
One client system I maintain (Laravel + MariaDB on the same machine) suddenly started returning 504 Gateway Timeout on every page at once, including the login page. I checked everything from RAM to table sizes. In the end, the cause was a single query that had been stuck for 54 minutes on a MyISAM table with just over a hundred thousand rows. This happened twice before I pieced together the full sequence, so I wrote down both the mechanism and the fixes.
The database names, table names, and process numbers in this article are all fictitious. The commands, figures, and sequence of events are real.
Symptoms: 504 on Every Page, with Plenty of RAM Still Free
My first three guesses were all wrong: insufficient RAM, an oversized table, and missing indexes. In fact, 9.5 GB of RAM was free, the locked table was tiny, and every index on that table was still there. The query simply wasn't using them. (I covered indexes that exist but cannot be used in a separate article on cross-database charsets, since that was the upstream cause of this case.)
504s on every page at once usually don't mean every page is slow. They mean every page is waiting for the same thing. If you see this, go straight to PROCESSLIST before investigating RAM or CPU.
The One Tool to Know: information_schema.PROCESSLIST
During the incident, I started with the shortest version because I needed an answer within seconds.
-- เวอร์ชันสั้นที่ใช้จริงตอนเกิดเหตุ
SELECT ID, TIME, STATE, INFO
FROM information_schema.PROCESSLIST
WHERE TIME > 3;
Once I had some breathing room, I used the full version. It is much easier to read because it removes newlines from INFO and sorts by query age.
SELECT ID, USER, HOST, DB, COMMAND, TIME, STATE,
       LEFT(REPLACE(INFO, '\n', ' '), 160) AS QUERY_HEAD
FROM information_schema.PROCESSLIST
WHERE COMMAND <> 'Sleep' AND TIME > 3
ORDER BY TIME DESC;
The column to learn to read is STATE, because it separates the "victims" from the "cause" for you.
Rows whose state is Waiting for table metadata lock or Waiting for table level lock are victims. There can be dozens of them, enough to make your eyes glaze over. Killing these won't fix anything, because new connections will soon pile up in their place. The cause is the row with an unusually high TIME and a blank state or Sending data.
Another command to run alongside this checks which tables are currently in use. This is the most straightforward check for MyISAM.
SHOW OPEN TABLES WHERE In_use > 0;
Then check which engine that table uses and how large it actually is. This was where I realized my guesses had been wrong all along.
-- เช็คว่าตารางใน mirror เป็น engine อะไร ใหญ่แค่ไหนจริง ๆ
SELECT TABLE_SCHEMA, TABLE_NAME, ENGINE, TABLE_ROWS,
       ROUND((DATA_LENGTH+INDEX_LENGTH)/1024/1024,1) AS MB
FROM information_schema.TABLES
WHERE TABLE_SCHEMA IN ('mirror_db', 'mirror_db2', 'app_db')
ORDER BY MB DESC;
The result showed that the table responsible was ENGINE=MyISAM, roughly 30 MB in size, with about 119,701 rows. It was so small that I could hardly believe it could take down the entire site.
Three Locking Layers, Each Working Differently
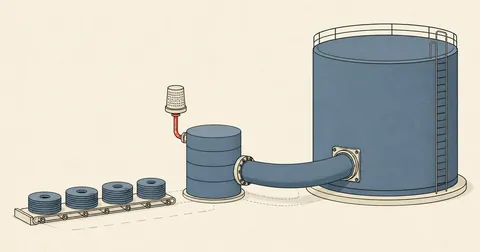
row lock + MVCC
Locks only the relevant rows. MVCC lets readers read an older snapshot. Long SELECTs don't block writers, and writers don't block SELECTs.
table locks only
Only table-level locks. A running SELECT = a READ lock on the whole table. Anyone wanting to write or change the structure must wait until it finishes. There is no MVCC to work around it.
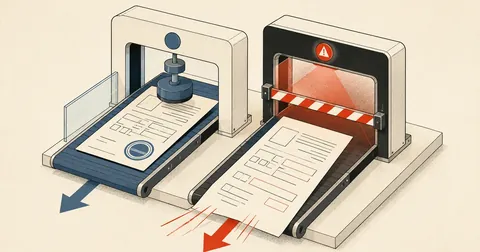
The third layer people overlook is the metadata lock (MDL). It sits above the storage engine. MySQL/MariaDB uses it to prevent a table's structure from changing while a statement is running. Commands such as RENAME ALTER DROP need an exclusive MDL first, which they can obtain only after the statement holding a shared MDL (the stuck SELECT in this case) finishes.
The key is that the MDL queue is FIFO. Normally, a new SELECT should be able to read the table without trouble. But once a RENAME is waiting in the queue, all new requests must line up behind it. As a result, ordinary SELECTs that have done nothing wrong have to wait too.
The Chain Reaction That Took Down the Whole Site
The query responsible looked roughly like this. It started from a mirror table with no index on the join column, and also used ORDER BY on a column from another table, so the optimizer chose a full scan plus filesort.
-- ผิด: เอาตาราง mirror (MyISAM, ไม่มี index บนคอลัมน์ที่ join) เป็นตัวตั้ง
--      แล้วยัง ORDER BY คอลัมน์ของอีกตารางหนึ่ง
SELECT ...
FROM mirror_db2.submit_log r
JOIN app_db.job_register c ON c.ref_no = r.visit_no
ORDER BY c.doc_date DESC;
Interestingly, the same codebase had a query of exactly the same kind that escaped the problem. The only difference was a WHERE clause limiting the date range.
$rows = $this->db()->select("
    SELECT a.ref_no, a.owner_id, pt.person_id, a.type_code, p.name type_name,
           a.amount charge, a.open_date, a.doc_date,
           TRIM(CONCAT(COALESCE(pt.fname,''),' ',COALESCE(pt.lname,''))) person_name
    FROM mirror_db.doc_head a
    LEFT JOIN mirror_db2.submit_log r ON r.ref_no = a.ref_no AND r.dept='IP'
    LEFT JOIN mirror_db.type_ref  p  ON p.type_code = a.type_code
    LEFT JOIN mirror_db.person    pt ON pt.owner_id = a.owner_id
    WHERE a.doc_date BETWEEN ? AND ? AND r.ref_no IS NULL AND a.amount > 0
    ORDER BY a.amount DESC", [$start, $end." 23:59:59"]);
I consider the first kind of query a time bomb. When there was little data, it finished in 2 seconds. After two years of data growth, that became 54 minutes without anyone changing a single line of code.
The Trigger: A Staging Table + RENAME Intended for Zero Downtime
On the cron side, I mirrored data from the source system onto the same machine as the website. The method was to dump into a staging table named <ตาราง>__new, then swap it in with a single RENAME TABLE, intending to keep the site available during sync.
# full reload 1 ตาราง ผ่าน staging table แล้ว rename (ออกแบบให้เว็บไม่ล่มระหว่าง sync)
reload(){ # db table [where]
  db=$1; t=$2; where=$3
  stage="${t}__new"
  old="${t}__old"
  mariadb "$db" -e "DROP TABLE IF EXISTS \`$stage\`" 2>>"$LOG" || true
  if mariadb-dump $SRC $DUMPOPT ${where:+--where="$where"} "$db" "$t" 2>>"$LOG" \
       | sed -E "s/(DROP TABLE IF EXISTS|CREATE TABLE|INSERT INTO|ALTER TABLE|LOCK TABLES) \`$t\`/\1 \`${t}__new\`/g" \
       | sed -E "$FIXCS" \
       | mariadb "$db" 2>>"$LOG"; then
    if [[ "$(table_exists "$db" "$stage")" != "1" ]]; then
      echo "$(ts) reload FAIL $db.$t (missing stage table $stage)" >>"$LOG"
      return 1
    fi
    if [[ "$(table_exists "$db" "$t")" == "1" ]]; then
      if ! mariadb "$db" -e "DROP TABLE IF EXISTS \`$old\`;
        RENAME TABLE \`$t\` TO \`$old\`, \`$stage\` TO \`$t\`;
        DROP TABLE IF EXISTS \`$old\`;" 2>>"$LOG"; then
        echo "$(ts) reload FAIL $db.$t (rename failed; keeping existing table)" >>"$LOG"
        mariadb "$db" -e "DROP TABLE IF EXISTS \`$stage\`" 2>>"$LOG" || true
        return 1
      fi
    else
      if ! mariadb "$db" -e "RENAME TABLE \`$stage\` TO \`$t\`;" 2>>"$LOG"; then
        echo "$(ts) reload FAIL $db.$t (initial rename failed)" >>"$LOG"
        return 1
      fi
    fi
    echo "$(ts) reload OK   $db.$t" >>"$LOG"
  else
    mariadb "$db" -e "DROP TABLE IF EXISTS \`$stage\`" 2>/dev/null
    echo "$(ts) reload FAIL $db.$t" >>"$LOG"
    return 1
  fi
}
The line that triggered it was RENAME TABLE \$t` TO `$old`, `$stage` TO `$t`;`. This works safely on a normal day. But with a SELECT stuck, it turned "one slow page" into "the whole site is down" by blocking the MDL queue.
The cron job ran hourly at minute 5, with flock already in place to prevent overlapping runs.
# /etc/cron.d/app-mirror
SHELL=/bin/bash
PATH=/usr/local/bin:/usr/bin:/bin
5 * * * * root /usr/bin/flock -n /tmp/app-hourly.lock -c '/usr/local/bin/app-hourly.sh' >> /var/www/app/storage/logs/mirrorsync.log 2>&1
Immediate Fix: One Command
- Run SELECT ID,TIME,STATE,INFO FROM information_schema.PROCESSLIST WHERE TIME>3; to get an overview first.
- Find the ID with an unusually high TIME that is not one of the rows whose state is waiting, because those are victims.
- KILL that one process, then wait a few seconds for the queue to clear.
- Check the mirror log to confirm that RENAME finished. Look for reload OK in the log file.
- Measure page load time to confirm recovery (mine returned to 0.3-0.7 seconds).
- Clean up any __new / __old tables left over from failed runs.
KILL <id>;          -- ฆ่าทั้ง connection (ที่ใช้จริงตอนนั้น)
KILL QUERY <id>;    -- ฆ่าเฉพาะ query ปัจจุบัน เก็บ connection ไว้ (ปลอดภัยกว่าเวลามี transaction)
If you want an automated cleanup command ready to use, this one-liner works. It kills only queries older than 600 seconds that do not belong to the system itself.
mariadb -N -e "SELECT ID FROM information_schema.PROCESSLIST \
  WHERE COMMAND<>'Sleep' AND TIME>600 AND USER<>'system user'" \
| while read id; do echo "killing $id"; mariadb -e "KILL QUERY $id"; done
Permanent Fixes, in Order of Payoff
The first and most worthwhile change is to stop using MyISAM for the mirror. Once it uses InnoDB, long SELECTs will no longer block other sessions' DDL.
ALTER TABLE mirror_db2.submit_log ENGINE=InnoDB ROW_FORMAT=DYNAMIC;
If there are dozens of tables, have information_schema generate the full set of statements, then run them all at once.
SELECT CONCAT('ALTER TABLE `',TABLE_SCHEMA,'`.`',TABLE_NAME,
              '` ENGINE=InnoDB ROW_FORMAT=DYNAMIC;') AS stmt
FROM information_schema.TABLES
WHERE ENGINE='MyISAM'
  AND TABLE_SCHEMA IN ('mirror_db','mirror_db2');
But changing the existing tables alone is not enough, because the next mirror run will dump the original structure back as MyISAM. The pipeline must be changed upstream so the tables are created as InnoDB from the start.
# ของเดิมในสคริปต์ (จัดการ charset + row format ของ InnoDB อยู่แล้ว)
FIXCS='s/CHARSET=tis620/CHARSET=utf8mb4/g; s/CHARACTER SET tis620/CHARACTER SET utf8mb4/g; s/tis620_thai_ci/utf8mb4_unicode_ci/g; s/tis620_bin/utf8mb4_bin/g; s/ENGINE=InnoDB /ENGINE=InnoDB ROW_FORMAT=DYNAMIC /g'

# สิ่งที่ต้องเพิ่มเพื่อฆ่า MyISAM ให้สิ้นซาก
FIXCS="$FIXCS"'; s/ENGINE=MyISAM/ENGINE=InnoDB ROW_FORMAT=DYNAMIC/g'
The second change is to remove all unbounded cross-db JOINs from web pages. I moved the slowest page to read a single summary table owned by the app, with the calculations done ahead of time during cron, so the page no longer needs to join across databases. The third change is to add indexes on the actual join keys on both sides.
-- ฝั่ง mirror: คีย์ที่หน้าเว็บใช้ join/filter
ALTER TABLE mirror_db2.submit_log
  ADD INDEX idx_ref (ref_no),
  ADD INDEX idx_visit (visit_no),
  ADD INDEX idx_ym (ym);
The fourth thing I had overlooked all along was timeouts. Setting them only on the client is not enough; they need to be set on the server too.
SET SESSION max_statement_time = 30;      -- MariaDB (วินาที)
-- MySQL 8: SET SESSION max_execution_time = 30000;  (มิลลิวินาที, เฉพาะ SELECT)
Traps I Would Pay Particular Attention To
HTTP timeouts and PHP's max_execution_time only cut off the PHP side. They don't send a KILL to MariaDB. The query keeps running on the server, holding its locks as before. This was exactly why the incident happened a second time: I saw the browser time out and thought it was over.
My ad-hoc SQL tool already had write protection and a timeout, but it was incomplete: after timing out, it did not follow up with a KILL.
WRITE = re.compile(
    r"\b(insert|update|delete|drop|alter|create|rename|replace|truncate|"
    r"grant|revoke|load\s+data|into\s+outfile|lock\s+tables)\b",
    re.IGNORECASE,
)

def guard(sql: str) -> None:
    stripped = re.sub(r"--[^\n]*|/\*.*?\*/", "", sql, flags=re.DOTALL)
    m = WRITE.search(stripped)
    if m:
        sys.exit(f"REFUSED (read-only audit tool): พบคำสั่งเขียน '{m.group(0)}'")
Another trap caught me two days later: backup cron files. I had backed up the old cron file in /etc/cron.d/, naming it .bak.<timestamp>, and thought that was safe. Instead, cron ran both the old and new jobs at the same time. The two mirror jobs collided on the same staging table names, the entire set of mirror tables disappeared, and the site returned 500s. I had to recover by rerunning the whole mirror in full mode. The lesson is never leave backup cron files in /etc/cron.d. Move them to /root/disabled-cron/ only.
To prevent overlapping runs of the script itself, I added another layer of flock inside the script, rather than relying on cron alone.
if [[ "${MIRROR_LOCKED:-0}" != "1" ]]; then
  exec 9>/tmp/app-mirror.lock
  if ! flock -n 9; then
    echo "$(ts) ===== mirror skipped: another mirror is running =====" >>"$LOG"
    exit 75
  fi
  export MIRROR_LOCKED=1
fi
A Short Checklist to Copy and Use
1. Are there any ENGINE=MyISAM tables left in the database? 2. Do web pages have cross-database JOINs without a WHERE clause limiting the range? 3. Are the join keys indexed on both sides, and do their charsets match? 4. Has max_statement_time been set for the user the website uses? 5. Is flock in place both in cron and inside the script? 6. Are there any backup files in /etc/cron.d that can still run? 7. Is there a cron job checking PROCESSLIST and alerting on or killing queries that exceed the limit?
I haven't properly implemented that last item in this case yet. For now, it is just a one-liner I run manually. I intend to make it a cron job that runs every 5 minutes and sends a chat alert first, then decide how many seconds to allow before auto-killing. If you have a limit you actually use in your own system, feel free to share it. I'd like to know what others set theirs to. If I've left anything out of the explanation or made a typo, I'll come back and correct it later.
Want us to set this up?
Get help with server setup, configuration, migration, or troubleshooting. Save time for the work that matters.
Hit something like this? Stuck somewhere?
Come trade notes on the LinuxThai board

Comments 0
No comments yet — be the first