Every Layer Reported Success While the Output Was Garbage
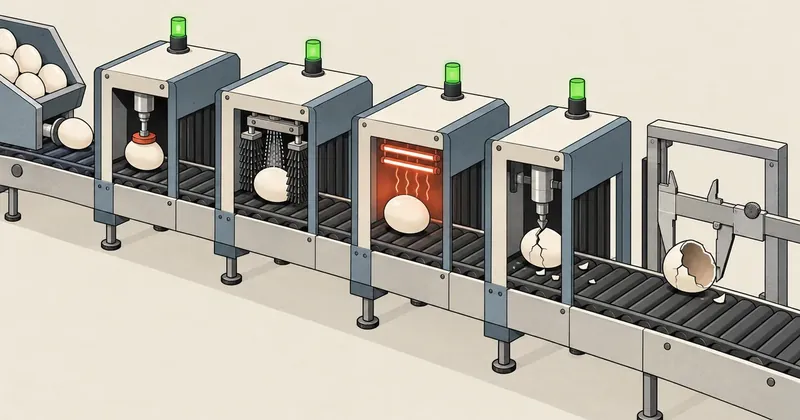
Success messages are usually true. The problem is that they are true of the stages still working, not the stages whose health we actually want to check.
One day, someone told me the content on the website was not updating. I opened the logs for the automated jobs and found tidy lines of success messages every day, without a single day missing. Only after tracing through each layer did I discover that four layers had failed on the same day, and all four reported success. No exceptions, no nonzero exit codes, no red lines anywhere.
What made this more troubling was that the four layers were separate systems, written in different languages and doing different jobs, yet they failed for the same structural reason. I treated this as one kind of mistake appearing in four places, rather than four bugs. This article takes that mistake apart and describes the rules I wrote to prevent it.
The website names, hostnames, paths, and service names in this article are examples. The symptoms and fixes are real.
Four Layers, One Day, Zero Errors
Working upstream from the downstream end, each layer had its own success message telling half the truth.
The first layer, the job that uploaded files to the host, reported 152 items successfully imported every day. That number was real. It was the number of items it had actually read in. But the step that pushed files to the destination machine failed every time because the program invoked a different file transfer program than intended, and its return value was discarded without anyone checking it. As a result, four days of content referenced files that did not exist on the destination machine.
The second layer, the job that collected data from a website requiring login, reported every day that the cookies were valid. That was true too, in its own way, because it checked whether the cookies existed, which is not the same as checking whether the session had expired. The website still served a page normally when not logged in. It was just a public preview page with cover information and no actual content. The system collected that preview page as data for thirteen days.
The third layer, the job that fetched new items from a feed, reported 34 items imported every day. But it received the same set every day because the feed sorted by relevance rather than date. Taking the first N items returned the same ones, and every one was then marked as already seen. In the end, not a single new item entered the system.
The fourth layer, the queue that sent jobs to an assistant for processing, reported that jobs had been picked up and moved into the completed folder. But not a single output file appeared. There was not even a partially written file.
Lesson One — Assert the Output, Not the Exit Code
What all these cases had in common was that I was measuring "execution" instead of "results." A command finishing without an error does not mean it did the work I wanted.
The call succeeded
A function returned without throwing an exception · the exit code was zero · a file was moved into the completed folder · the number of items read in · cookies exist in a file. These are all facts about the mechanics.
The output exists and is correct
The file expected at the destination actually exists and its size matches · the fetched page contains content indicating a logged-in session · the items received include at least one never seen before · the output file contains content that meets minimum criteria
The pattern I now enforce for every automated job is that it must end with a single verdict line and return a nonzero exit code if it fails.
def finish(problems: list[str]) -> None:
    """ทุกงานจบตรงนี้ที่เดียว — คำตัดสินอยู่ที่บรรทัด RESULT บรรทัดเดียวเท่านั้น"""
    if problems:
        print("RESULT: INCOMPLETE")
        for p in problems:
            print(f"PROBLEM: {p}")
        sys.exit(1)
    print("RESULT: OK")
    sys.exit(0)
The advantage of a fixed format is that I can monitor it with one line, without writing a separate log parser for each job.
# ตัวเฝ้าดูของทุกงานเป็นบรรทัดเดียวกันหมด
for f in /var/log/jobs/*.log; do
  tail -n 40 "$f" | grep -q '^RESULT: OK$' || echo "[ERR] $(basename "$f")"
done
The entire bug in the first layer came down to one return-value variable that nobody printed out to inspect. The file transfer program failed and faithfully returned a value saying so every time, but the calling code simply discarded it and carried on. The rule is simple: if a stage failing would invalidate the output, never discard its return value. Capture it, check it, and make a decision every time.
Lesson Two — Existing Does Not Mean Valid
The cookie case and the output file case were the same problem: I used "existence" as a substitute for "correctness" because it was much easier to check.
A file existing does not mean it is new. A new file does not mean it contains anything. Having content does not mean that content is what I asked for. Every skipped step leaves an opening for failure to slip in silently. My approach is to write a single function that answers "Has any real work been produced yet?" and always inspects the contents.
def has_real_output(kind: str, path: Path) -> bool:
    """ดูเนื้อในเสมอ ห้ามตัดสินจากการมีอยู่ของไฟล์"""
    if not path.exists():
        return False
    try:
        data = json.loads(path.read_text(encoding="utf-8"))
    except (json.JSONDecodeError, UnicodeDecodeError):
        return False                     # ไฟล์เสีย = ไม่มีผลงาน ไม่ใช่ error ที่ต้องโยน

    if kind == "translate":
        # ต้องมีรายการที่ได้หัวข้อยาวพอจะเป็นหัวข้อจริง ไม่ใช่ช่องว่างหรือขีด
        return any(len((it.get("title") or "").strip()) >= 8 for it in data)
    if kind == "digest":
        return len(data) > 0 and all(it.get("summary") for it in data)
    return bool(data)
The same principle applies to sessions. Do not ask whether cookies exist. Ask whether the page received contains something visible only when logged in, such as the username in the top corner or a button that logged-out users cannot see. If those things are missing, the session is not logged in, regardless of how complete the cookie file is.
MARKERS = ("data-user-id=", 'id="composer"', 'class="account-menu"')

def looks_logged_in(html: str) -> bool:
    # หน้าสาธารณะกับหน้าที่ล็อกอินแล้วมีโครงต่างกัน ตรวจที่โครง ไม่ใช่ที่คุกกี้
    return any(m in html for m in MARKERS)
Lesson Three — mtime Is Not Work Produced
The fourth case is my favorite because it taught me something deeper than the others. The job queue decided whether a job was complete with a single line.
done = bool(m and m > started) # m = mtime ของไฟล์ผลลัพธ์
It looks very reasonable at first. The output file was touched after I dispatched the job, so the job must be complete. The problem was that the preceding step had written that output file a few seconds before dispatch. When the queue first checked, three minutes after dispatch, it saw an mtime newer than the recorded time and immediately declared the job complete, even though the processor had not touched the file once.
The consequences cascaded. The job was marked complete. The next step picked up a file with no content and produced an empty result. The publisher then had nothing to send, and the website stayed stuck without an error anywhere along the entire pipeline.
In my first fix, I switched from checking mtime to inspecting file contents and immediately hit another problem — on days when there was nothing to do, the file would never be touched. The "work produced" condition could therefore never become true. The queue stalled for seventy-five minutes until it timed out. The problem was that I was trying to squeeze three situations into two boolean values.
The fix was to stop using a boolean and return three states, which better reflected reality.
from enum import Enum

class Produced(str, Enum):
    NOWORK = "nowork"   # ไม่มีอะไรให้ทำตั้งแต่แรก -> จบทันที ไม่ต้องรอ
    DONE   = "done"     # มีผลงานจริง ผ่านเกณฑ์เนื้อหา -> จบแบบสำเร็จ
    WAIT   = "wait"     # ยังไม่มีผลงาน -> รอต่อจนหมดเวลาแล้วรายงานว่าไม่สำเร็จ

MIN_WORK_SEC = 60

def produced(kind: str, path: Path, started: float, pending: int) -> Produced:
    if pending == 0:
        return Produced.NOWORK
    if not has_real_output(kind, path):
        return Produced.WAIT
    m = path.stat().st_mtime
    # ต้องใหม่กว่าเวลาที่สั่งงาน และต้องผ่านเวลาขั้นต่ำด้วย กัน race กับไฟล์ที่เพิ่งเขียนก่อนหน้า
    if m <= started or (time.time() - started) < MIN_WORK_SEC:
        return Produced.WAIT
    return Produced.DONE
MIN_WORK_SEC is a buffer for cases where the preceding step writes the file very close to dispatch time. It does not fix the root problem. Inspecting the file contents does that. But it helps guard against cases where the existing contents happen to meet the criteria before the new job starts.
After the fix, I made every log line end with the reason for its verdict, such as [translated 40/40], [307 headings present], or [no items to process]. This means I can open the log and immediately tell whether the system actually did any work or simply passed through, without opening the output files myself. Those numbers in brackets are what make an abnormal day stand out.
Lesson Four — Do Not Trust an Order You Did Not Define
The third case taught me something different: I had assumed that the data received was sorted by time, even though the source had never promised that. The feed sorted by relevance, so taking the first N items returned the same set every day.
I did two things. First, I sorted the items myself using the date field after receiving them. Second, I added a check for whether the current run had actually found anything new. If not, the run counted as unsuccessful.
from email.utils import parsedate_to_datetime

# ผิด: เรียงสตริงวันที่แบบ RFC-822 = เรียงตามชื่อวันในสัปดาห์ (Fri, Mon, Sat...)
# items.sort(key=lambda it: it["pubDate"], reverse=True)

# ถูก: แปลงเป็น datetime ก่อนแล้วค่อยเรียง
def pub_dt(it):
    try:
        return parsedate_to_datetime(it["pubDate"])
    except (TypeError, ValueError):
        return datetime.min.replace(tzinfo=timezone.utc)

items.sort(key=pub_dt, reverse=True)

fresh = [it for it in items if it["link"] not in seen]
if not fresh:
    finish(["รอบนี้ไม่ได้รายการใหม่เลยสักชิ้น (ฟีดอาจค้างหรือเรียงผิด)"])
The line commented above is exactly where I got caught. Dates in this kind of feed are strings beginning with the day of the week. Sorting them as strings therefore sorts alphabetically by weekday name, producing an order that looks random but stays consistent. It is easy to miss because it produces no error and the results look as though they are sorted by something.
At first, I thought of fixing this by requesting data more often, which was the wrong idea and would only waste quota. When I tried increasing the number of items per page while keeping the same number of requests, I got several times more new items because they were sitting just beyond the cutoff. Before increasing frequency, check whether you are seeing everything.
The Rules I Have Used for Every Automated Job Since
Here is the short list. All of these are very cheap to add on day one and very expensive to add later, once things have already gone missing.
- Every job ends with a single RESULT line and exits with a nonzero value if it fails. That line alone carries the verdict. Nobody should infer it from other lines.
- If a stage failing would invalidate the output, never discard its return value.
- Always inspect the contents. Do not just check that a file, cookie, row, or process exists.
- Use three states instead of true or false when reality includes a "nothing to do" case.
- Have a completeness check for each piece of work. Everything referenced by the content must actually exist at the destination, rather than merely being expected to exist.
- Do not trust an order the source has not promised. Sort it yourself and verify it yourself.
- An empty result or None is usually a temporary symptom, not the truth. Retry before letting it reduce the actual value.
I implemented the completeness check in rule five as a single function that both repairs and reports, because if it can fix the problem, it should. But if it cannot, it must say so loudly.
def gate(refs: list[str], local_dir: Path, remote_dir: str) -> list[str]:
    """ของทุกชิ้นที่เนื้อหาอ้างถึง ต้องอยู่ปลายทางจริง — ซ่อมได้ก็ซ่อม ซ่อมไม่ได้ก็ต้องดัง"""
    problems = []
    for name in refs:
        if remote_has(remote_dir, name):
            continue
        src = local_dir / name
        if not src.exists():
            problems.append(f"no-local: {name}")
            continue
        rc = push(src, remote_dir)          # รับค่ากลับมาเสมอ ห้ามทิ้ง
        if rc != 0 or not remote_has(remote_dir, name):
            problems.append(f"still-missing: {name} (rc={rc})")
    return problems
How to Catch Silent Failures in Practice
I will close with two diagnostic techniques I have used repeatedly, with success every time.
The first is to compare the destination artifacts' last modification times with the data collection dates. If the newest file in the destination folder is dated the last time I ran the job manually, that means the automation has been dead since that day. It is the most accurate way to find the date it died without reading a single log line.
# ปลายทางหยุดหายใจตั้งแต่เมื่อไหร่
ssh host 'ls -lt --time-style=+%Y-%m-%d /srv/site/assets/ | head -n5'

# นับชิ้นงานต่อวัน ถ้ามีวันที่หายไปเป็นช่วง แปลว่าเส้นนั้นตายช่วงนั้น
ssh host 'ls --time-style=+%Y-%m-%d -l /srv/site/assets/ | awk "{print \$6}" | sort | uniq -c | tail -n20'
The second is that the failure must be reproduced in the environment where it occurs. The first layer's bug stayed hidden for so long because whenever I went in and tested it manually, it worked correctly. It failed when the scheduler invoked the job, using a different PATH and set of environment variables from the ones present when I typed the command myself.
What worked was putting a job directly into that same queue, having it run the commands I wanted to investigate and redirect the output to a file, then reading that file afterward.
# วางเป็นงานให้ตัวจัดตารางเวลาเรียก อย่ารันเองด้วยมือ
{
  echo "=== whoami/env ตอนถูกเรียกจริง ==="
  whoami
  echo "PATH=$PATH"
  command -v scp ssh python3
  echo "=== ลองขาที่สงสัยจริง ๆ ==="
  scp -v /tmp/probe.txt user@host:/tmp/ 2>&1 | tail -n 20
  echo "rc=$?"
} > /var/log/jobs/probe-from-scheduler.log 2>&1
The contents of that file answered everything in three lines, giving me the answer I had failed to find during two days of manual investigation.
My takeaway is that every stage in an automated system whose output nobody verifies will eventually fail, and nobody will know when it does. The success messages I see every day are always true. They are just true of the stages still working, not the ones I want to know about. If you have automation that has been running for a long time without anyone checking the final output, take a look. If I have left anything out of the explanation or made any typos, I will come back and fix them later.
Hit something like this? Stuck somewhere?
Come trade notes on the LinuxThai board

Comments 0
No comments yet — be the first