9 Users Were Never Backed Up Because the Cron List Never Changed
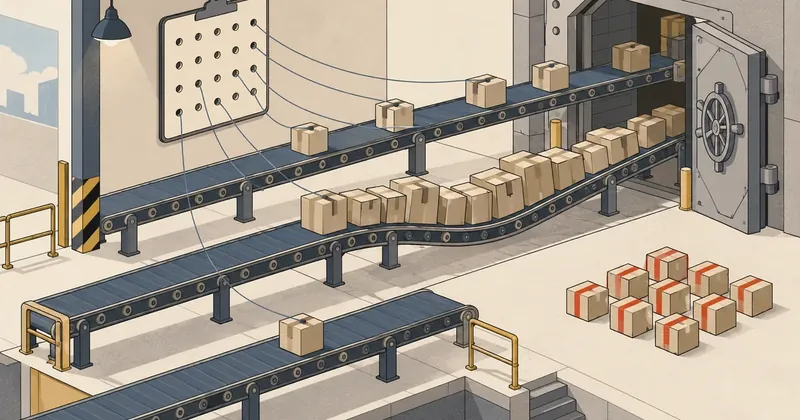
A backup system that succeeds every night only tells you that the scheduled work finished. It does not tell you whether that work still matches what is on the machine, and a list written four months ago cannot know about users created last month.
1-minute summary
- Symptom / problem
- Nine users were never backed up because the cron user list was never updated, while health checks kept passing.
- Who should read
- DirectAdmin admins whose backup crons use an explicit user list.
- Fix in short
- Write an audit script that compares real users against the select lists in backup_crons.list, regroup greedily, and add a daily check for orphaned users.
The server owner asked me one thing: I had initially spread the backup load across groups, but more domains had been added since then, so the list had probably changed. I ran a read-only audit on that DirectAdmin server, intending only to check whether the groups were still balanced. The result was worse than I expected: 9 users were missing from every cron, meaning they had never been backed up since they were created. Among them were a new billing system and a recently completed production website.
All usernames, hostnames, and paths in this article have been replaced with example values. The sizes, user counts, and file structure are real.
The system I designed, and the question nobody asked for four months
DirectAdmin's Admin Backup on this server writes per-user tarballs (.tar.zst) to NFS on a backup host, with separate folders named for each day. When I migrated the server, I designed it around 3 groups of roughly equal size, running on Monday, Wednesday, and Friday at 01:00, leaving Sunday for a snapshot of the entire VM. An old cron running on Tuesday, Thursday, and Saturday was also left over from the previous system. I covered this setup in Rebuilding DirectAdmin Backups with NFS and POSIX ACL.
The user lists for each group are not in root's crontab. They are in DA's own file.
ls -l --time-style=long-iso /usr/local/directadmin/data/admin/backup_crons.list
# -rw------- 1 diradmin diradmin ... 05-21 ... backup_crons.list
The owner must be diradmin and the permissions must be 600. Each line is one cron, in a URL-encoded format like <id>=action=backup&hour=1&minute=0&dayofweek=1&...&select0=userA&select1=userB..., where dayofweek 1 is Monday through to 6 for Saturday. Details on writing this file are in Setting Up DirectAdmin Admin Backup Cron from the CLI. This time, I was interested in just one thing: the date line. The file was last modified on May 21 and had not been touched for almost 4 months, even though new users kept being created during that time.
The health check on this server checked two things: whether the backup ran, and whether the destination ACL still allowed writes. Both checks passed every day for four months because the cron really did process its entire list. Neither check asked whether every user on the server was on that list.
The audit script: comparing actual users against select entries in every cron
I wrote a short, read-only Python script that did three things: parsed every line of backup_crons.list to extract the selectN values, compared them against the actual DA user lists across all resellers, and added each user's home directory size.
#!/usr/bin/env python3
# /root/audit_backup_cover.py -- อ่านอย่างเดียว ไม่แก้ไฟล์ใด
import os, re, subprocess, sys
from urllib.parse import parse_qsl

CRONS = '/usr/local/directadmin/data/admin/backup_crons.list'
USERS = '/usr/local/directadmin/data/users'      # หนึ่งโฟลเดอร์ต่อหนึ่ง user ทุก reseller

def cron_groups():
    groups = {}
    with open(CRONS, encoding='utf-8') as f:
        for line in f:
            line = line.strip()
            if '=' not in line:
                continue
            cid, qs = line.split('=', 1)
            kv = parse_qsl(qs, keep_blank_values=True)      # ถอด URL-encode ให้เสร็จ
            dow = dict(kv).get('dayofweek', '*')
            runs = 7 if dow == '*' else len(dow.split(','))  # จำนวนรอบต่อสัปดาห์
            sel = [v for k, v in kv if re.fullmatch(r'select\d+', k)]
            groups[cid] = {'dow': dow, 'runs': runs, 'users': sel}
    return groups

def home_gb(user):
    r = subprocess.run(['du', '-sb', f'/home/{user}'], capture_output=True, text=True)
    return int(r.stdout.split()[0]) / 1e9 if r.stdout else 0.0

real = sorted(os.listdir(USERS))
size = {u: home_gb(u) for u in real}
groups = cron_groups()

covered, weekly = {}, 0.0
for cid, g in groups.items():
    gb = sum(size.get(u, 0.0) for u in g['users'])
    weekly += gb * g['runs']
    print(f"cron {cid}: dow={g['dow']:<6} users={len(g['users']):>3} {gb:7.1f} GB/รอบ")
    for u in g['users']:
        covered[u] = covered.get(u, 0) + g['runs']

orphans = [u for u in real if u not in covered]
print(f"\nuser จริง {len(real)} ราย ข้อมูล {sum(size.values()):.1f} GB ส่งต่อสัปดาห์ {weekly:.1f} GB")
print(f"ไม่อยู่ใน cron ใดเลย {len(orphans)} ราย รวม {sum(size[u] for u in orphans):.2f} GB")
for u in orphans:
    print(f"   [ORPHAN] {u:<12} {size[u]:6.2f} GB")
print("ถูก backup มากกว่า 1 รอบต่อสัปดาห์:",
      sum(1 for n in covered.values() if n > 1), "ราย")
sys.exit(1 if orphans else 0)
This script had a lesson of its own. The first time, I uploaded it to /tmp on the server. The owner told me to move it immediately because this was a shared host: /tmp was visible to other users on the machine, and the script's output listed every user on the server along with their size. I moved it under /root and set its permissions to 700.
install -m 700 -o root -g root audit_backup_cover.py /root/audit_backup_cover.py
rm -f /tmp/audit_backup_cover.py
/root/audit_backup_cover.py | tee /root/backup-cover.log && chmod 600 /root/backup-cover.log
The results: three problems in one file
The first problem was 9 orphaned users totaling 1.91 GB. All were created after May 21, exactly the date the file was last modified. Their combined size was under 2 GB, so there was no way to notice from destination storage usage. But that data included a new billing system and a production website. If the server had failed during those four months, there would have been no copies of this group's data anywhere.
The second problem was that the groups were no longer balanced. The three groups had been close in size when I designed them, but websites grow at different rates. This was what I found during the audit.
| cron | User count | Size per run | Runs per week |
|---|---|---|---|
| Monday | 26 | 126.8 GB | 1 |
| Wednesday | 23 | 70.8 GB | 1 |
| Friday | 22 | 64.0 GB | 1 |
| Old cron: Tuesday, Thursday, Saturday | 42 | 165.3 GB | 3 |
The third problem was duplication. Many users were in both their assigned weekday group and the old cron, so some were backed up as many as 5 times per week. The server held 205.7 GB of actual data, but the weekly volume transferred over NFS was 757.5 GB (126.8 + 70.8 + 64.0 plus 165.3 multiplied by 3).
Overall, the system was doing roughly 3.7 times the necessary work relative to the actual data, while doing no work at all for the 9 newest users. Both problems had the same cause: the lists were written once, and nobody went back to review them.
One-way drift: deletions remove entries automatically, creations do not add them
During this work, I found a fact about DA that explained why the file drifted in only one direction. When a user was deleted through DA (CMD_API_SELECT_USERS with delete), I prepared a script to remove that name from backup_crons.list. Before I could run it, the file had already shortened on its own. DA automatically removed the deleted user from every cron. The coverage figures matched again at 76/76 without me having to do anything.
But creation does not work that way. Whether a user is created directly in DA or provisioned by the billing system, no step adds the name to a backup cron. When I traced the origins of those 9 users, 8 had been created directly in DA, bypassing the billing system, and no step required adding them to backups after creation.
The result of this asymmetry is that the cron list can only shrink; it never grows with the server. As time passes, the gap between actual users and backed-up users only widens. The missing users are always the newest ones, which are often the projects their owners care about most at that moment.
What I fixed immediately, and the file permissions issue along the way
Coverage could not wait, so I handled it before rebalancing: I added all 9 orphaned users, plus 1 new customer account, to the Friday group, which was the lightest. I then reran the audit and got 77/77 coverage.
L=/usr/local/directadmin/data/admin/backup_crons.list
B=/root/backup_crons.list.$(date +%F-%H%M)
cp -p "$L" "$B" && chmod 600 "$B"          # สำรองก่อนแก้ และห้ามให้ใครอ่านได้
stat -c '%a %U:%G %n' "$L" /root/backup_crons.list.*

# หลังแก้บรรทัดของกลุ่มวันศุกร์ (ต่อ selectN ท้ายบรรทัด ไล่เลขต่อจากตัวสุดท้าย)
chown diradmin:diradmin "$L" && chmod 600 "$L"
/root/audit_backup_cover.py | tail -5
That stat command exposed another issue. A backup copy of the file made earlier had permissions of 644, meaning any user on the server could read it, and it contained the server's entire user list. I changed it to 600 immediately.
cp without -p creates a new file according to the caller's umask, often resulting in 644. The original is 600, but the copy sitting beside it is readable by everyone on the server. On a shared host, this also applies to audit scripts, output, and logs. They belong under /root, not /tmp.
Greedy regrouping and its cost
Once coverage was complete, I looked at balance. I used the simplest method that gave usable results: greedy bin-packing, sorting users from largest to smallest and placing each one into whichever group was lightest at that point.
def pack(size, k=3):
    """size: {user: GB}  ->  k กลุ่มที่ขนาดรวมใกล้กันที่สุดเท่าที่วิธี greedy ทำได้"""
    bins = [{'gb': 0.0, 'users': []} for _ in range(k)]
    for user, gb in sorted(size.items(), key=lambda x: -x[1]):   # ใหญ่ไปเล็ก
        lightest = min(bins, key=lambda b: b['gb'])              # กลุ่มที่เบาที่สุดตอนนี้
        lightest['gb'] += gb
        lightest['users'].append(user)
    return bins

for i, b in enumerate(pack(size, 3), 1):
    print(f"กลุ่ม {i}: {len(b['users']):>3} users {b['gb']:6.1f} GB")
With this server's data, each group came to about 68.6 GB. If I also retired the old cron, the weekly transfer volume would drop from 757.5 GB to 205.7 GB, a reduction of 73%. The numbers looked very good, but I did not apply the change myself because it had a cost that was not measured in GB.
Duplicate backups, but more restore points
Users in both a weekday group and the old cron have up to 4-5 restore points per week. If a file breaks on Wednesday, Tuesday's copy is still available. The cost is transferring 757.5 GB per week and a Monday group nearly twice the size of Friday's.
73% less data, but only one restore point
Every user is backed up 1 time per week, with about 68.6 GB per group. If a file becomes corrupted one day after backup day, the nearest copy is from the previous week. Changes made during that interval could mean losing almost 7 days of data.
I sent the owner both sets of figures along with the options for a decision. I proposed two options: 3 groups as before, or 6 groups spread across Monday through Saturday. As of this writing, neither option has been applied. The only change made so far is the coverage fix. Personally, I do not think the server administrator should decide this alone. The number of restore points is an agreement with the data owner, not a performance tuning setting.
Proposal: a daily orphaned-user check
This section is a proposal; it has not been installed on the server yet. But I think it is necessary, because as long as creating a user does not automatically add the name to a cron, the same problem will return with every new account. The audit script above already returns exit code 1 when it finds orphaned users, so it can be hooked directly into a daily cron.
# /etc/cron.d/backup-coverage  (ข้อเสนอ ยังไม่ได้ติดตั้งจริง)
# 07:15 ทุกวัน ถ้ามี user ที่ไม่อยู่ใน backup cron ใดเลย ให้ส่งเมลเตือนพร้อมรายชื่อ
MAILTO=""
15 7 * * * root /root/audit_backup_cover.py > /root/backup-cover.log 2>&1 || grep ORPHAN /root/backup-cover.log | mail -s "[WARN] backup coverage drift" [email protected]
This is the sequence I will use on every DirectAdmin server I manage from now on.
- Compare the last modification date of
backup_crons.listwith the creation date of the newest user. If the file is older, users are definitely missing. - Run the read-only audit script. Keep the script and output under
/rootwith permissions of 700 and 600, not in/tmp. - Add orphaned users to the lightest group first. Coverage does not need to wait for a decision on balance.
- Back up the file with
cp -p, then check the permissions of every backup copy present. They must be 600. - Calculate new groups using greedy allocation, then send both sets of figures to the data owner to choose, including both the reduction in volume and the loss of restore points.
- Hook the orphaned-user check into a daily cron, and add an "add to backups" step to user creation through both DA and billing.
What failed here was not the backup system. It had faithfully followed the list it was given all along. What failed was that nobody owned that list. DA handles only half of it: deletions. For creations, a person or script has to do the work, and a health check that checks whether a job succeeded will never see work that was never requested. Offsite uploads failing while the job reports success are another layer, which I covered in Backups Succeeded Every Night, but There Were No Offsite Copies for 3 Weeks. Feel free to take the audit script and adjust the paths for your own server. If I left anything out or made a typo, I will come back and fix it later.
Want us to set this up?
Get help with server setup, configuration, migration, or troubleshooting. Save time for the work that matters.
Hit something like this? Stuck somewhere?
Come trade notes on the LinuxThai board
Comments 0
No comments yet — be the first