Locked Out by a Firewall Change over SSH: The Flush Rollback Trap
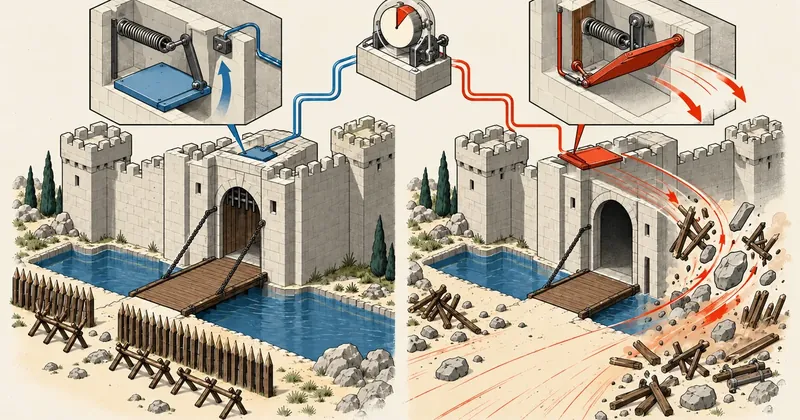
A rollback mechanism written to prevent mistakes can itself become a vulnerability if it restores a state worse than the one I was trying to avoid.
1-minute summary
- Symptom / problem
- The 180-second rollback in a firewall push script used nft flush ruleset, which could leave the machine with no firewall at all.
- Who should read
- People pushing nftables rules to a VPS over SSH.
- Fix in short
- Roll back to the previous working ruleset instead of flushing everything, and test the rollback by breaking the rules on purpose.
I had two VPS instances handling the web side for a client and needed to switch them to an nftables firewall with policy drop while also moving the SSH port. Changing a firewall over SSH is one of the riskiest jobs I have done, because one mistake means locking myself out of a remote machine. So I wrote apply_firewall.sh around an escape plan first: a 180-second rollback timer to recover access. But while reviewing the security of the first version myself, I found a trap in that recovery mechanism, and I want to explain the whole thing.
The hostnames, IP addresses, ports, and rules in this article are all fictional examples (192.0.2.x, 198.51.100.x, SSH port 2200). You can use the ideas, but changing a real machine's firewall over the network can leave you unable to log in if something goes wrong. Always try it first on a test machine you can access another way. For a machine you do not own, ask its owner before proceeding.
Why changing a firewall over SSH is so risky
The reason is simple: the SSH session where I am typing commands is my only route into the machine. Once the new policy drop rules are loaded, if they do not let my session through (for example, I forgot to put my address in the whitelist, or moved the SSH port while the rules still point to the old one), the existing session will not disconnect immediately because there is an established rule, but new connections will no longer get in. Once this session drops, I have no way back.
So I designed the script as a sequence, with a way back in place at every step before making the actual change.
- scp the new rules up as nftables.conf.new without touching the current file yet
- Write an sshd drop-in (port, keys-only, forwarding disabled, MaxAuthTries 4), then run sshd -t before reloading
- Write fail2ban jail.local with ignoreip taken from the same whitelist file as the firewall, so it cannot ban my own address
- Run nft -c -f to check the new file's syntax without applying it
- Back up the current file as nftables.conf.bak
- Use systemd-run to set a 180-second timer to restore the .bak file
- mv the new file into place, then apply it with nft -f
- From the admin machine, open a new SSH session on the new port
- Only if that succeeds, stop the timer, enable nftables, and restart fail2ban
The script sequence, from the admin machine
The part that does the work is bash running on the admin machine. I have shortened it and changed the names to make the example easier to read. The important part is the sequence.
#!/bin/bash
# apply_firewall.sh  รันจากเครื่องแอดมิน  (host-a คือ alias ใน ~/.ssh/config)
set -euo pipefail
HOST=host-a
NEW_PORT=2200

scp nftables.conf "$HOST:/etc/nftables.conf.new"          # 1

ssh "$HOST" 'bash -s' <<'REMOTE'
set -e
# 2 sshd drop-in แล้วทดสอบก่อน reload
cat > /etc/ssh/sshd_config.d/10-hardening.conf <<'EOF'
Port 2200
PasswordAuthentication no
AllowTcpForwarding no
X11Forwarding no
MaxAuthTries 4
EOF
sshd -t && systemctl reload ssh

# 4 ตรวจ syntax ก่อนของจริง
nft -c -f /etc/nftables.conf.new

# 5 สำรองไฟล์ปัจจุบัน (ถ้ามี)
[ -f /etc/nftables.conf ] && cp -a /etc/nftables.conf /etc/nftables.conf.bak

# 6 ตัวย้อนกลับ 180 วินาที
systemd-run --quiet --unit=fw-rollback --on-active=180 /bin/sh -c \
 'if [ -f /etc/nftables.conf.bak ]; then cp -f /etc/nftables.conf.bak /etc/nftables.conf; nft -f /etc/nftables.conf; else nft flush ruleset; fi'

# 7 ใช้กฎใหม่
mv -f /etc/nftables.conf.new /etc/nftables.conf
nft -f /etc/nftables.conf
REMOTE

# 8 session ใหม่ บนพอร์ตใหม่ ต่อจริงด้วย key ไม่ reuse connection เดิม
if ssh -p "$NEW_PORT" -o BatchMode=yes -o ControlPath=none -o ConnectTimeout=10 "$HOST" true; then
  # 9 ผ่านแล้วเท่านั้น ถึงยกเลิกตัวย้อนกลับ
  ssh -p "$NEW_PORT" "$HOST" 'systemctl stop fw-rollback.timer && systemctl enable nftables && systemctl restart fail2ban'
  echo '[OK] applied, rollback timer stopped'
else
  echo '[ERR] new session failed: leave the timer running, it restores the old rules in <=180s'
  exit 1
fi
There are two things to remember. First, if your ssh config enables ControlMaster, you need ControlPath=none when testing the new session. Otherwise, the "new session" will run over the existing connection, which proves nothing. Second, in step 8 I use key-only authentication on the new port. If it connects, that means the new rules really allow a new connection through, rather than just an old session still hanging on.
The trap in the first version: rolling back with flush ruleset
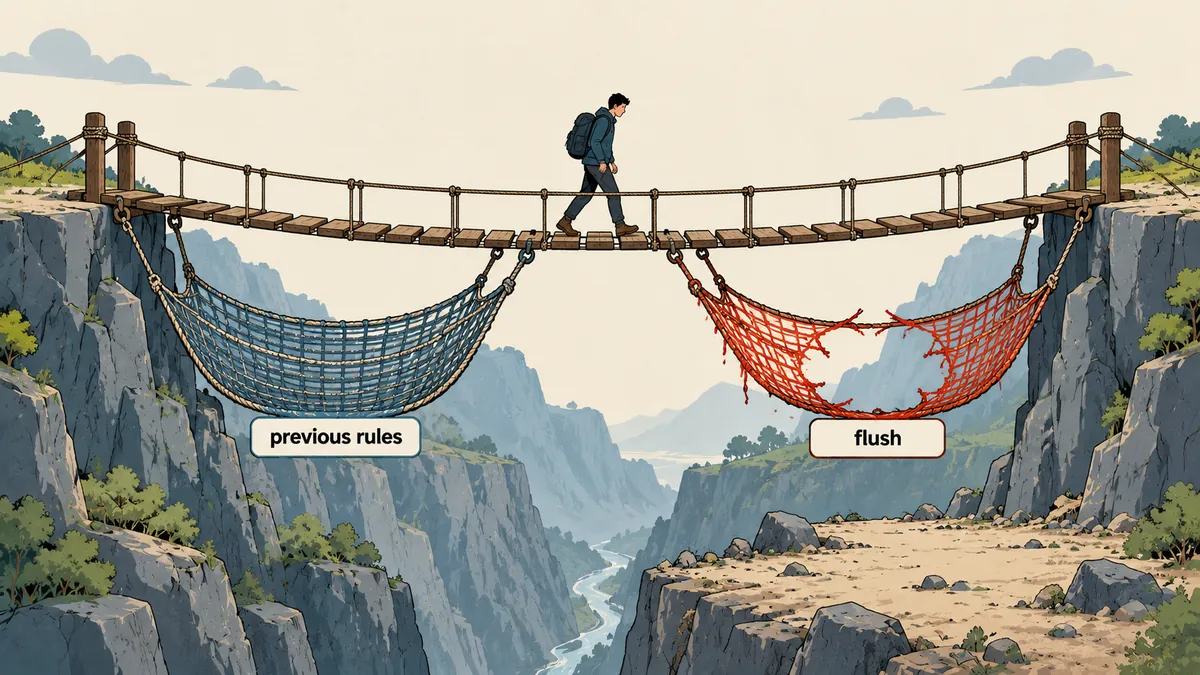
This is the main point of the article. In the first version I wrote, the rollback was simply nft flush ruleset. My thinking at the time was, "If the new rules are wrong and I get locked out, clear the rules so I can get back in." That sounds reasonable, and if the only question is whether I can log in, it does the job. The problem is that I can get in because everyone can get in.
With no chains at all, nftables has no rules and no policy drop. Every packet gets through. Put simply, the timer I wrote to recover access would "clear the entire firewall," leaving every port exposed just when I could not log in. And nobody might even know the machine was exposed, because I thought I had only locked myself out. I caught this while reviewing the script's security.
Rollback = nft flush ruleset
Access is restored, but because no firewall remains. The policy becomes accept, and every port is open to the entire internet while the admin still cannot fix things. The mistake leaves the machine worse off than before the work began.
Rollback = restore the original file, then nft -f
Returns to the rules in use before the change. Policy drop remains, and access works as it did before starting. Flush is used only when there was no original file at all, meaning the starting state already had no firewall.
My own conclusion is that there is one rule for an escape plan: it must return to a previously safe state, rather than one that is easy to get into. And I need to think from the perspective of an outsider who does not know I am currently locked out. Call that rule whatever you like, but I call it "rolling back must be no worse than doing nothing."
There is another point I need to mention to avoid confusion. The fixed version restores the backed-up "file," which assumes the rules running before the change match that file. If you have manually changed the live rules without saving them to the file, the rollback will not restore those live rules. Save the live rules to a file before using a script like this.
flush ruleset in the rules file is not the problem
Notice that the nftables.conf file I generate also starts with flush ruleset, but that is fine here. The reason is that when loaded with nft -f, the whole file runs as one transaction. If anything in the file is wrong, none of it is applied, and all the old rules remain intact. That differs from a standalone flush in the timer, with no rules following it to replace what was cleared.
The rules I generate from the source lists with a script have this structure (a fictional example, not the actual rules).
#!/usr/sbin/nft -f
flush ruleset

table inet fw {
  set wl4 { type ipv4_addr; flags interval; auto-merge; elements = { 203.0.113.10 } }
  set wl6 { type ipv6_addr; flags interval; auto-merge; }
  set web4 { type ipv4_addr; flags interval; auto-merge; }
  set web6 { type ipv6_addr; flags interval; auto-merge; }

  chain input {
    type filter hook input priority 0; policy drop;
    ct state established,related accept
    ct state invalid drop
    iif lo accept
    ip saddr @wl4 accept                 # whitelist เข้าได้ทุกพอร์ต
    ip6 saddr @wl6 accept
    meta l4proto { icmp, ipv6-icmp } accept
    tcp dport { 80, 443 } ip saddr @web4 accept     # เว็บ เฉพาะจาก set ที่อนุญาต
    udp dport 443 ip saddr @web4 accept
    limit rate 5/minute log prefix "fw-drop: "      # log การ drop แบบจำกัดอัตรา
  }
  chain forward { type filter hook forward priority 0; policy drop; }
  chain output  { type filter hook output priority 0; policy accept; }
}
I use policy drop for input, drop for forward, and allow output as usual. I cover the set used to allow web ports only from certain sources separately in a set for allowing CDNs and bots. For scanning the system with other tools, see debian-server-security-scan, and my broader security principles for letting AI work over SSH are in claude-ssh-safe.
fail2ban and the same whitelist file
One small detail that saves me is taking fail2ban's ignoreip from the same whitelist file used to generate the firewall rules. If there are two separate files, one day someone will update one and forget the other, and fail2ban will ban an address the firewall allows, or vice versa. My settings are bantime of 1 hour, findtime of 10 minutes, maxretry 5, an nftables action, and systemd as the backend.
# /etc/fail2ban/jail.local  (ตัวอย่าง ignoreip สร้างจากไฟล์ whitelist ตอน apply)
[DEFAULT]
bantime  = 1h
findtime = 10m
maxretry = 5
backend  = systemd
banaction = nftables
ignoreip = 127.0.0.1/8 ::1 203.0.113.10

[sshd]
enabled = true
port    = 2200
After making the planned changes, I also accept the new values into the AIDE baseline using the same accept script, so the daily reports are not cluttered with differences I deliberately introduced. Otherwise, when something really is wrong, I will not be able to find it.
Testing the rollback by deliberately getting it wrong
I do not trust a rollback mechanism until I have seen it work. My test is to use a test machine first, deliberately set incorrect rules that block the SSH port, and wait the full 180 seconds. I need to see two things together: I can log in again, and nft list ruleset still shows the previous policy drop rules rather than an empty ruleset.
# บนเครื่องทดลอง หลังตั้งกฎผิดแล้วรอครบ 180 วินาที
nft list ruleset | head -n 20          # ต้องเห็น table inet fw และ policy drop ของกฎเดิม
systemctl list-timers 'fw-rollback*'  # timer ควรหายไปหลังทำงานเสร็จ
journalctl -u fw-rollback.service -n 20 --no-pager
The rollback is scheduled before applying the new rules, the rollback restores the original file rather than flushing, the new session is tested over an actual new connection, the timer is canceled only on success, deliberately incorrect rules have been tested on a test machine and the previous rules were seen to return, and fail2ban's ignoreip comes from the same file as the firewall.
Some VPS providers offer an emergency console as another way into the machine, but I do not treat that as the main plan, because it may not be available everywhere, and when I need it is usually when it is slowest. The main plan is a script that can roll back on its own without anyone coming to help.
What I would do the same way again
If I have to change a remote machine's firewall again, I will follow this sequence: always check syntax first, back up the original, schedule the rollback before touching the live setup, and have it restore the previous state rather than an empty one. Then prove access by opening an actual new session before canceling the rollback. As for flush, I am not ruling it out everywhere. It is fine in a rules file loaded all at once, but it must not be a standalone command in the recovery mechanism. Each site can add whatever else suits it, such as an immediate alert when the timer runs. If I have missed anything, or the rules on your machine differ from the example, I will come back and update this later.
Want us to set this up?
Get help with server setup, configuration, migration, or troubleshooting. Save time for the work that matters.
Hit something like this? Stuck somewhere?
Come trade notes on the LinuxThai board
Comments 0
No comments yet — be the first