Ten Edits, Ten IndexNow Requests: Queue and Debounce in Laravel
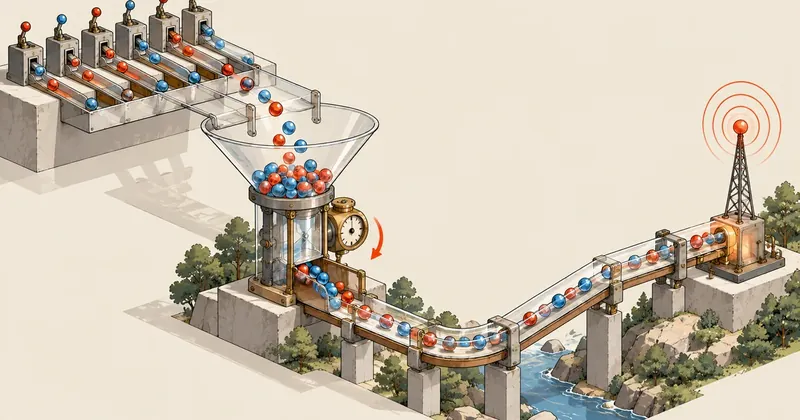
Notifying search engines is not about sending requests as quickly as possible. It is about deciding correctly what to report, when and how often, and making those decisions at send time rather than save time.
1-minute summary
- Symptom / problem
- Firing IndexNow on every save of a Laravel site gets blocked and wastes quota
- Who should read
- Laravel site owners who want Bing to know right away when pages change
- Fix in short
- Queue URLs in a table via model events, wait for 120 seconds of quiet, send in batches from a cron every 5 minutes, with backoff rules and a sitemap safety net
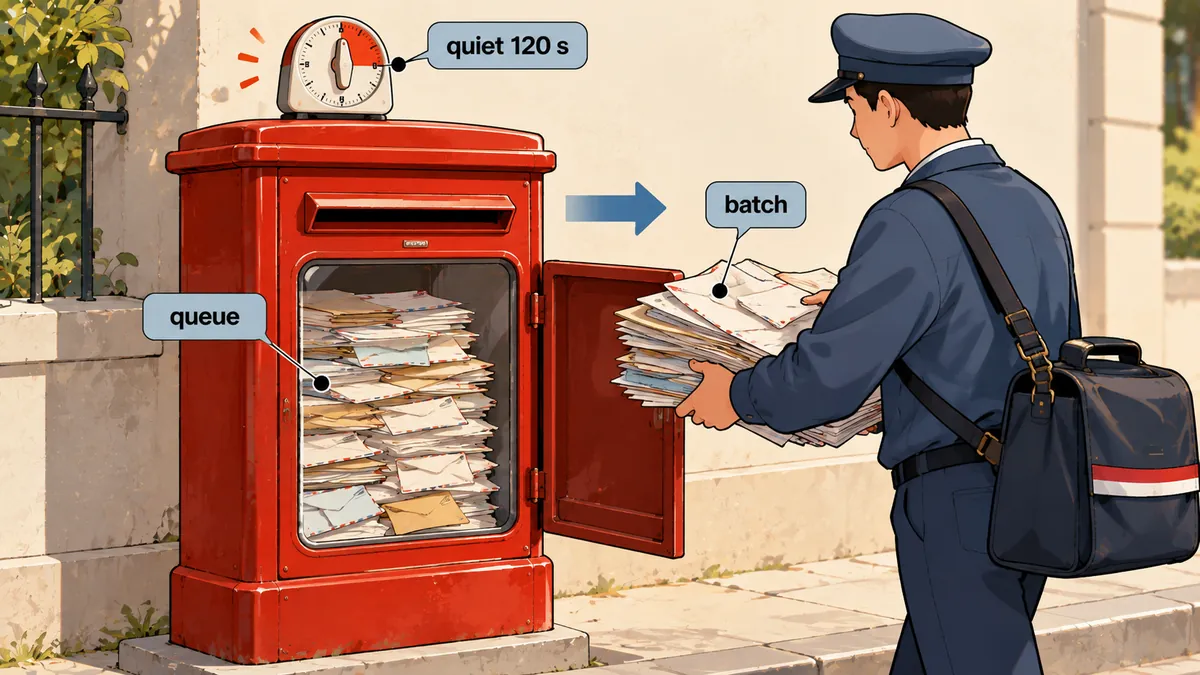
A client's Laravel site has several types of content pages and two versions, th and en. The owner wanted Bing and the search engines in the IndexNow network (Bing, Yandex, Seznam, Naver through a single shared endpoint) to know immediately when a page was added, changed or removed. I started with the simplest approach: send an IndexNow request when saving in the admin. The result was ten requests for ten consecutive edits, and if the page had not been translated yet and was noindex, I should not have reported it at all. My solution was "queue, debounce and decide at send time," all in one class, with the comment at the top of the file serving as its specification.
The IndexNow key file is a text file placed under the website root and is public by design. But I do not include the key value, domain name or actual URL count for this project in the article. All examples use example.com and placeholders.
What goes into the queue: model events and columns that do not count
The triggers are registered in AppServiceProvider alongside the sitemap hooks. I queue URLs under four conditions: creation, publication, unpublication, deletion, or "public columns changed." That last condition needs careful thought, because an admin might change the sort order, toggle is_featured, edit keywords or simply cause updated_at to change, none of which affects what search engines see. I therefore calculate a fingerprint of the public columns, while admin columns go into a per-model ignore list and do not count.
// app/Providers/AppServiceProvider.php  (ชื่อโมเดลเป็นตัวอย่าง)
public function boot(): void
{
    foreach ([Page::class, Article::class, Service::class] as $model) {
        $model::saved(fn ($m) => IndexNow::onSaved($m));
        $model::deleted(fn ($m) => IndexNow::onDeleted($m));
    }
}
// app/Support/IndexNow.php  (ย่อ)
private const IGNORE = [
    Page::class => ['sort_order', 'is_featured', 'keywords', 'created_at', 'updated_at'],
];

private static function fingerprint(array $attrs, array $ignore): string
{
    $public = array_diff_key($attrs, array_flip($ignore));
    ksort($public);
    return md5(json_encode($public, JSON_UNESCAPED_UNICODE));
}

public static function onSaved(Model $m): void
{
    $ignore = self::IGNORE[$m::class] ?? ['created_at', 'updated_at'];

    // saved ถูกเรียกก่อน syncOriginal เลยยังเห็นค่าเก่าอยู่ใน getOriginal()
    if (! $m->wasRecentlyCreated
        && self::fingerprint($m->getOriginal(), $ignore) === self::fingerprint($m->getAttributes(), $ignore)) {
        return;                                   // แก้แต่คอลัมน์ฝั่งแอดมิน ไม่ต้องแจ้ง
    }
    if ($m->wasChanged('slug')) {
        self::queue($m->getOriginal('slug') ? self::urlFor($m, old: true) : null, 'moved');   // URL เก่าเข้าคิวเป็นถอด
    }
    self::queue(self::urlFor($m), $m->wasRecentlyCreated ? 'created' : 'changed');
}

public static function queue(?string $url, string $reason): void
{
    if (! $url) return;
    DB::table('indexnow_urls')->upsert(
        [['url' => $url, 'url_hash' => sha1($url), 'reason' => $reason,
          'changed_at' => now(), 'queued_at' => now()]],
        ['url_hash'],                              // หนึ่งแถวต่อ URL
        ['reason', 'changed_at']                   // แก้ซ้ำแค่ดันเวลาเปลี่ยนล่าสุดออกไป
    );
}
I added two rules beyond ordinary model events. First, when a slug changes, the old URL must also enter the queue with the reason "moved" so search engines can see that the old page is gone. Second, writing or deleting an English translation queues only the en URL, without pulling in the Thai URL as well. There are five reasons that mean "page removed": unpublished, deleted, moved, gone, and untranslated. For these rows, I use the reason itself as the hash.
Two tables and one log file
Everything lives in two tables. The first, indexnow_urls, stores one row per URL, with url_hash as a unique key. The second, indexnow_pushes, logs each request, and there is also a storage/logs/indexnow.log file.
CREATE TABLE indexnow_urls (
  id             BIGINT UNSIGNED AUTO_INCREMENT PRIMARY KEY,
  url            VARCHAR(2048) NOT NULL,
  url_hash       CHAR(40)      NOT NULL,
  reason         VARCHAR(24)   NOT NULL,      -- created, changed, moved, unpublished, deleted, gone, untranslated
  changed_at     DATETIME      NOT NULL,      -- เนื้อหาเปลี่ยนล่าสุดเมื่อไร ใช้ debounce
  queued_at      DATETIME      NOT NULL,
  last_pushed_at DATETIME      NULL,
  UNIQUE KEY uq_url_hash (url_hash)
);

CREATE TABLE indexnow_pushes (
  id        BIGINT UNSIGNED AUTO_INCREMENT PRIMARY KEY,
  pushed_at DATETIME     NOT NULL,
  url_count INT          NOT NULL,
  status    SMALLINT     NOT NULL,
  note      VARCHAR(255) NULL
);
I personally prefer letting the DB enforce uniqueness, without writing my own "is this already in the queue?" check. A single upsert handles it, and ten repeated edits still produce just one row. The last-change timestamp keeps moving forward, restarting the debounce timer each time.
Rules at send time: debounce, min_gap, repeat_after
All values live in config/indexnow.php. I checked the file, and the three main values are:
- debounce 120 seconds A recently changed URL must remain quiet for the full interval first, so ten consecutive edits become one request.
- min_gap 3,600 seconds A URL whose content changes again is sent at most once during this interval.
- repeat_after 86,400 seconds An unchanged URL (a full push, manual submission or sitemap check) is not sent again within one day.
- Maximum 10,000 URLs per POST This is the protocol limit. Anything beyond it is split into batches.
// เลือก URL ที่ถึงเวลาส่ง
$due = DB::table('indexnow_urls')
    ->where('changed_at', '<=', now()->subSeconds(config('indexnow.debounce')))   // 120
    ->orderBy('changed_at')
    ->get()
    ->filter(function ($r) {
        if ($r->last_pushed_at === null) return true;
        $since   = now()->timestamp - strtotime($r->last_pushed_at);
        $changed = strtotime($r->changed_at) > strtotime($r->last_pushed_at);
        return $changed
            ? $since >= config('indexnow.min_gap')        // 3600
            : $since >= config('indexnow.repeat_after');  // 86400
    })
    ->take(10000);
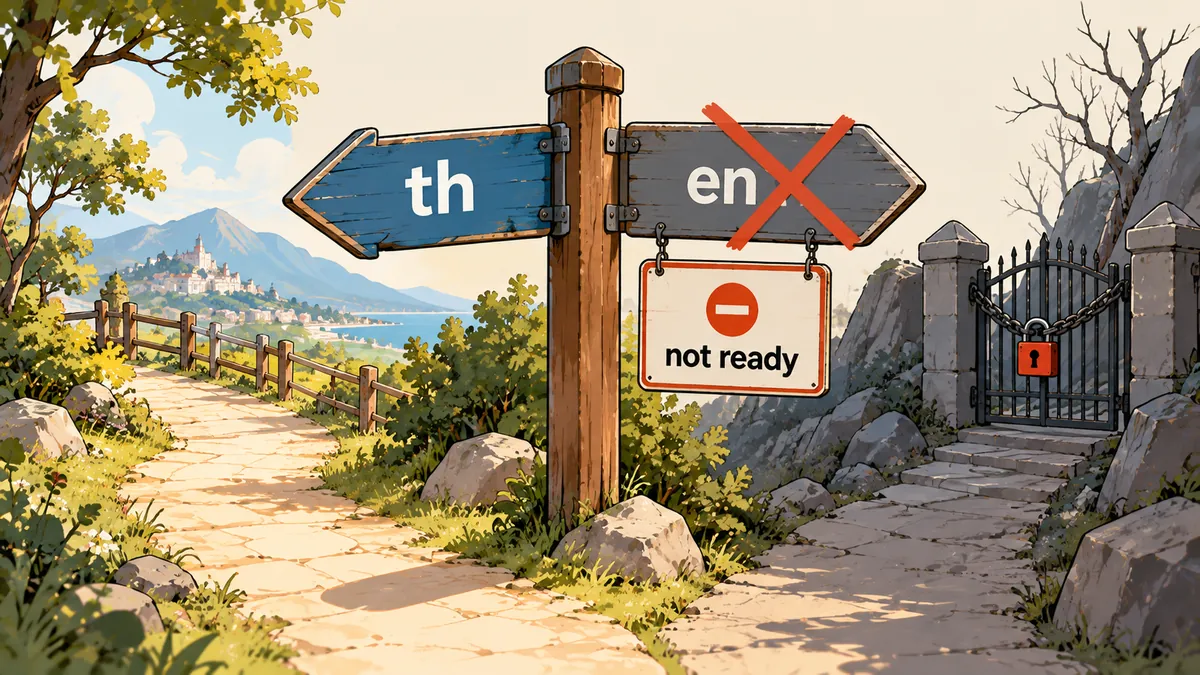
Another rule that led me to decide at send time rather than save time concerns untranslated en pages. These are noindex and absent from the sitemap, so they are not sent: doing so would tell search engines to visit pages I do not want indexed. The exception is a page that has already been sent. In that case, I send it again as "removed" so the engine fetches it again and sees a 404. I covered incomplete translations and the sitemap on the translation side in The site translation queue says nothing to send.
Which responses mean back off, and which mean stop
I divide API responses into two broad groups: "can retry" and "retrying will fail the same way." I treat 200 and 202 as accepted and record last_pushed_at.
| Response | Meaning | Action |
|---|---|---|
| 403 with SiteVerificationNotCompleted in the message | The engine has not fetched the key file yet, often during the first few minutes after a new key is introduced | Keep the URL in the queue and back off for 15 minutes |
| 429 | Requests sent too frequently | Back off for 60 minutes |
| 0 or 5xx | Connection failed, or there is a problem on the engine's side | Back off for 15 minutes |
| Other 400, 403, 422 responses | Malformed request, incorrect key or URL on the wrong host | Log it and do not retry |
$status = $resp->status();          // ต่อไม่ได้ให้จับ exception แล้วใช้ 0
$body   = $resp->body();

match (true) {
    in_array($status, [200, 202])
        => self::markPushed($batch),
    $status === 403 && str_contains($body, 'SiteVerificationNotCompleted')
        => Cache::put('indexnow:backoff', true, now()->addMinutes(15)),   // URL ยังอยู่ในคิว
    $status === 429
        => Cache::put('indexnow:backoff', true, now()->addMinutes(60)),
    $status === 0 || $status >= 500
        => Cache::put('indexnow:backoff', true, now()->addMinutes(15)),
    default
        => self::logAndDrop($batch, $status, $body),                       // 400/403/422 อื่น ไม่ลองซ้ำ
};
I do not retry the last group because the same request will fail the same way every time. Retrying wastes resources and may lead to a stricter block. I follow the same principle here as in the API throttling discussion in batch API throttle: separate errors that can be retried from those that should not be.
Safety net: compare the sitemap when the combined fingerprint changes
Model events do not cover everything. Bulk SQL that modifies tables directly, scheduled articles reaching their publication time, and new static pages that are not models all bypass events. I therefore added a second safety net to the same cron job: compare the sitemap, but only when the combined fingerprint (the md5 of the per-file fingerprints) changes, rather than on every run. This is much cheaper and still catches what slips through.
public static function sitemapSafetyNet(): void
{
    $files = Sitemaps::fingerprints();                 // ['pages' => '...', 'articles' => '...']
    $total = md5(json_encode($files));
    if ($total === Cache::get('indexnow:sitemap_fp')) {
        return;                                        // ไม่เปลี่ยน ข้าม
    }
    foreach (Sitemaps::allUrls() as $url) {
        if (! DB::table('indexnow_urls')->where('url_hash', sha1($url))->exists()) {
            self::queue($url, 'changed');
        }
    }
    Cache::forever('indexnow:sitemap_fp', $total);
}
The cron setup itself is simple:
# crontab ของ user เว็บ  (path เป็นตัวอย่าง)
*/5 * * * * cd /home/webuser/app && php artisan indexnow:push >> storage/logs/indexnow.log 2>&1
Safety and testing
Outside production, I disable actual sending: dev and test still queue URLs normally but do not call the API, keeping test data from reaching search engines. Another site on the same system calls submitFor(), which binds its own root and key and discards URLs belonging to other hosts. The key is stored as a file at the website root and can be overridden through .env, but a key file with the matching name must actually exist, or it will produce the 403 described in the table.
I have not checked how many URLs have actually been sent for this project, so I have included no volume figures in the article. The only numbers shown are configuration values, which I verified against the file.
Five lessons
Send directly from the event
The simplest approach, but ten edits produce ten requests, pages that should not be reported get sent, and API errors can cause admin saves to fail.
Queue, debounce, decide at send time
The event only upserts one row. What to send and when is decided during the cron run using rules that can be changed in config.
First, do not send directly from events. Queue URLs and decide at send time. Second, define clearly "what does not count as a change" with an ignore list of columns. Third, reporting "removed" is as important as reporting "added." If a page disappears without notification, search engines will keep pointing to something that no longer exists. Fourth, separate errors that can be retried from those that should not be. Fifth, always have a safety net, because events do not cover bulk SQL. Personally, if I added anything else, it would probably be a dashboard summary showing how many URLs are waiting in the queue, depending on each site's needs. If I have missed anything in the explanation, or the numerical rules no longer match a newer config, I will come back and update the article later.
Want us to set this up?
Get help with server setup, configuration, migration, or troubleshooting. Save time for the work that matters.
Hit something like this? Stuck somewhere?
Come trade notes on the LinuxThai board
Comments 0
No comments yet — be the first