A Slow Chatbot from a Whole-Site Prompt: A Row-by-Row Index
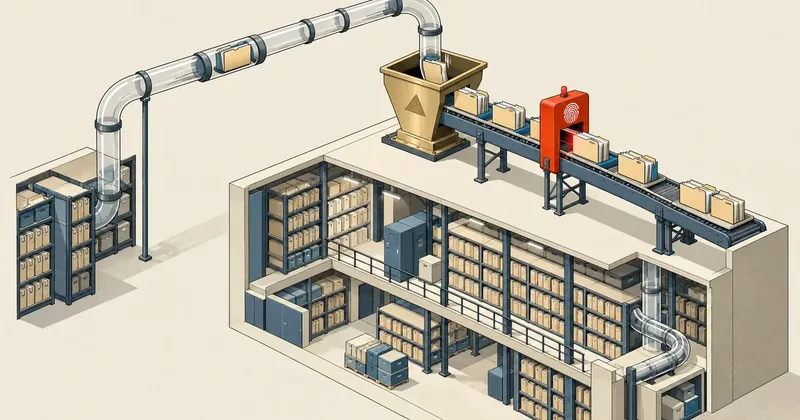
An oversized prompt is expensive on every turn. An empty prompt that leaves searching to the model is slow because it needs repeated tool calls. What works in practice is separating what the model needs to know every time from what it can look up when needed, then using hashes to avoid unnecessary cache invalidation.
1-minute summary
- Symptom / problem
- A chatbot carried the whole site in a prompt of about 110k tokens and still made several search tool calls.
- Who should read
- People building an LLM chatbot for a content-heavy site.
- Fix in short
- Build a knowledge index table updated row by row from model events, written only when the hash changes, with a hot part that is always in the prompt and the rest searched on demand.
A chatbot answering customers on one of my clients' websites was getting slower and slower, so I looked into what each question was consuming. I found that in the first version, I had put the entire site's content into the prompt: service pages, articles, team information, canned answers, and response guidelines, totaling around 110k tokens per turn. Whenever the site's content changed, the whole prompt cache was invalidated. It was both expensive and slow. I tried the opposite approach: keeping the prompt light and letting the model call search tools itself. That introduced another problem: it needed several searches before it could answer. This article covers how I settled on a middle ground that worked.
The timings and token counts in this article were measured using 8 test questions on one website, and the before-change numbers come from notes I took at the time. I can no longer verify them retrospectively. Use them as an order-of-magnitude comparison of the approach, not a promise that your website will get the same results.
The problem: neither stuffing in the whole site nor searching alone works
I'll start with the numbers I recorded, comparing the version that included the whole site with the revised version, measured on the same set of questions.
What stood out was that the time wasn't spent just writing the answer. Before the changes, each question needed around 10 search tool calls despite the prompt already being that large. The model wasn't sure where the information it needed was in that huge block, so it kept searching to confirm. After the changes, that dropped to 1 call per question.
Large prompt, easily invalidated cache
The model sees everything at once, but every time the site owner changes a single word on any page, the prompt text changes. The prompt cache can no longer be reused, and the full cost and latency return on the next turn.
Light prompt, but repeated calls
There is nothing to invalidate in the cache, but the model has to come up with a search query, retrieve and read the results, and sometimes search a second or third time because the first query missed. Every search adds a round trip.
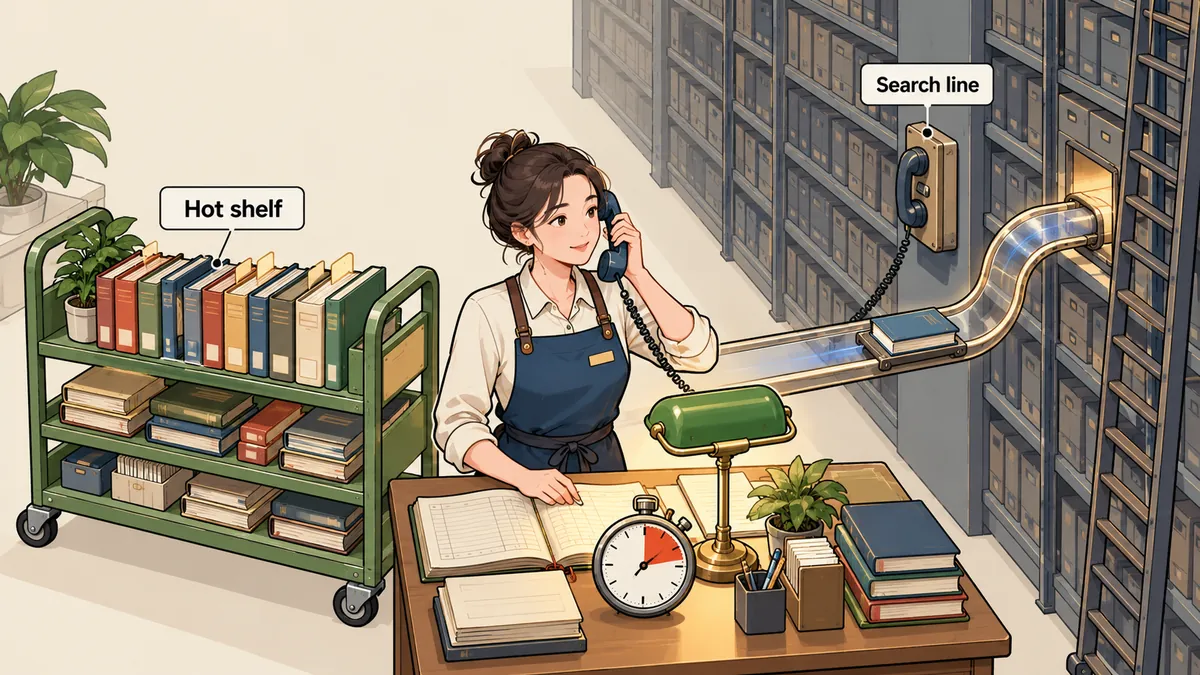
I chose a hybrid approach, splitting the knowledge into two groups: things customers ask about almost every day and things they ask about occasionally. The first group goes straight into the prompt; the second is searched when needed. If your site is small enough to include everything, that's your choice, but mine wasn't that small.
The index table: one row per content item per language
I created a knowledge_index table, with each row representing one content item in one language. The unique key consists of source_type, source_id, and locale. It stores the assembled text, ready to serve into the prompt, and an md5 hash of the data used to assemble it. Each content type (main products, services, articles, team members, canned answers, response guidelines, and general site information) has its own Mapper class that converts rows from the source table into text in a consistent format.
CREATE TABLE knowledge_index (
  id           BIGINT UNSIGNED AUTO_INCREMENT PRIMARY KEY,
  source_type  VARCHAR(40)  NOT NULL,
  source_id    BIGINT       NOT NULL,
  locale       VARCHAR(8)   NOT NULL,
  title        VARCHAR(255) NOT NULL,
  body         MEDIUMTEXT   NOT NULL,
  is_hot       TINYINT(1)   NOT NULL DEFAULT 0,
  content_hash CHAR(32)     NOT NULL,
  updated_at   TIMESTAMP    NULL,
  UNIQUE KEY uq_source (source_type, source_id, locale)
);
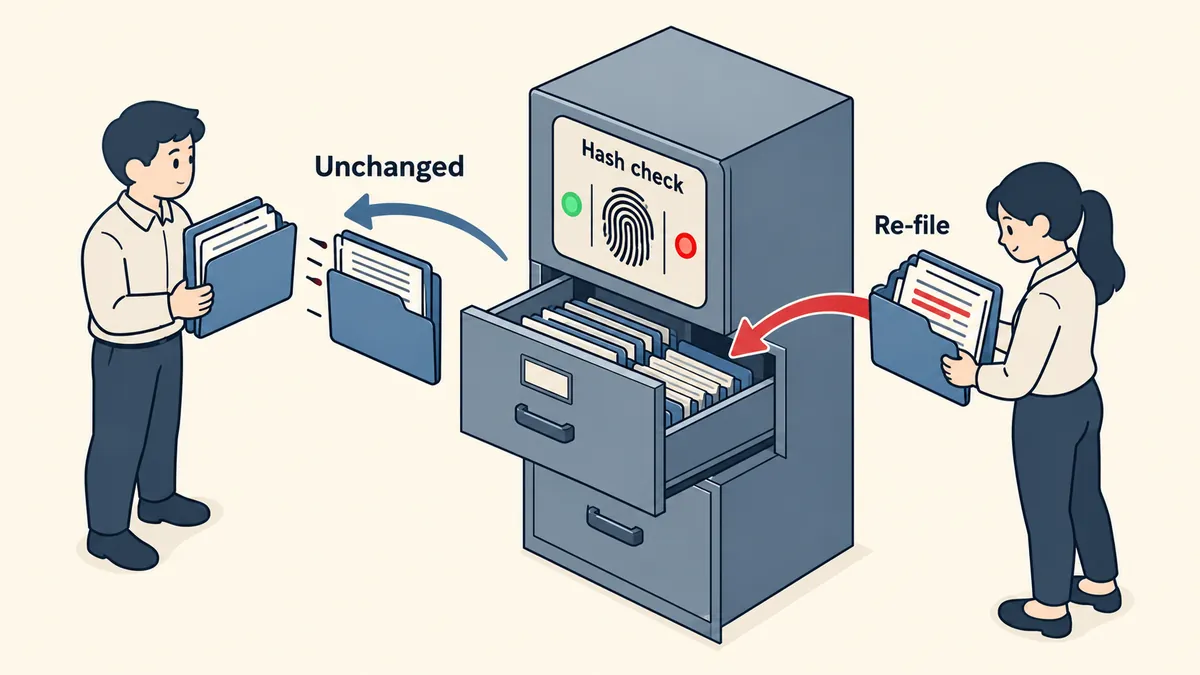
The one rule that keeps the cache stable is write a row only when its hash differs from the existing one. Saving again without an actual change (the site owner clicks save without editing anything, or an admin-side column such as the last-modified time changes) leaves the row untouched. The index version therefore stays the same.
public static function upsert(string $type, int $id, string $locale, array $row): void
{
    $hash = md5(json_encode($row, JSON_UNESCAPED_UNICODE));
    $key  = ['source_type' => $type, 'source_id' => $id, 'locale' => $locale];

    $old = DB::table('knowledge_index')->where($key)->value('content_hash');
    if ($old === $hash) {
        return;                       // ไม่มีอะไรเปลี่ยนจริง ไม่แตะแถว ไม่ขยับ version
    }

    DB::table('knowledge_index')->updateOrInsert($key, [
        'title'        => $row['title'],
        'body'         => $row['body'],
        'is_hot'       => $row['is_hot'] ? 1 : 0,
        'content_hash' => $hash,
        'updated_at'   => now(),
    ]);
}

public static function version(): string
{
    $all = DB::table('knowledge_index')
        ->orderBy('source_type')->orderBy('source_id')->orderBy('locale')
        ->pluck('content_hash')->implode('');
    return dechex(crc32($all));       // CRC32 ของ hash ทุกแถวต่อกัน
}
I use this version value as the endpoint's ETag and to tell whether the hot prompt block has changed. If no row's hash changes, the version stays the same, and every character of the prompt text stays the same. The prompt cache can therefore be reused.
Update one row at a time through model events, without rebuilding everything
The triggers are the saved and deleted model events on each source model, registered in one place when the app boots. When the site owner edits an article, the event invokes the article Mapper, assembles new text, and passes it through the upsert above, writing a single row if the hash differs or deleting the row if the source was deleted. It never reassembles the entire site.
foreach ($mappers as $modelClass => $mapper) {
    $modelClass::saved(fn ($m) => KnowledgeIndex::sync($mapper, $m));
    $modelClass::deleted(fn ($m) => KnowledgeIndex::forget($mapper, $m));
}
But events do not cover every path. Large SQL statements run directly, bulk imports, and changes that bypass the model do not fire events. I therefore added an artisan command for backfill as another route. It can be run as many times as needed because it uses the same upsert, writing only rows whose hashes have changed and deleting rows whose sources no longer exist.
# ชื่อคำสั่งเป็นชื่อสมมติ
php artisan knowledge:index                       # ซ่อมทั้งดัชนี เขียนเฉพาะแถวที่ต่าง
php artisan knowledge:index --only=article        # เฉพาะชนิดเดียว
php artisan knowledge:index --show=hot            # ดูข้อความส่วน hot ที่จะเข้า prompt
php artisan knowledge:index --search="ราคา ค่าส่ง"  # ลองค้นเหมือนที่บอทค้น
I use --show=hot most often because it shows exactly what the model will see. If the site owner complains that the bot's answer is wrong, I first check whether that information is in hot.
The hot section and its character cap
Rows flagged as hot always go into the prompt, but there has to be a cap. Otherwise, hot will grow back into the whole site again. I control this through a single config value, hot_cap, currently set to around 60,000 characters. If the assembled text exceeds it, I cut content according to priority. The rest hasn't disappeared; it is still searchable through the tool.
My criterion for deciding what belongs in hot is this: if the bot doesn't know this at the start of the turn, will its answer be wrong or look bad? Examples include general site information, response guidelines, and canned answers to frequently asked questions. I leave the details of individual pages that rarely come up to search.
The endpoint the bot uses to assemble its prompt accepts part as hot, guides, or all, along with locale, and returns ready-to-use text with an ETag equal to the index version. If the bot sends If-None-Match matching the current version, it returns 304 with no body. This lets me have the bot call it as often as needed without wasting bandwidth or reassembling the text.
curl -si 'https://example.com/api/bot/knowledge?part=hot&locale=th' \
     -H 'If-None-Match: "a1b2c3d4"'
# HTTP/1.1 304 Not Modified      <- ไม่มีอะไรเปลี่ยน ใช้ข้อความ hot เดิมใน prompt ต่อได้
Search: enough Thai support and a little typo tolerance
I wrote the search component (KnowledgeSearch) to handle Thai well enough for practical use, without anything elaborate. It has synonym groups from config. Latin-script terms match only "whole words," so line must not match online. It also tolerates Latin-script typos with a levenshtein distance of no more than 2 from configured synonyms. It uses idf weighting, giving rare terms more weight than terms found everywhere, multiplies title matches by 1.6, and ranks rows containing every required term group ahead of rows containing only some terms. I have already written separately about a search engine specifically for Thai in the article on Thai search with FTS5 trigram, so I won't repeat those details here.
Presearch: search before the model starts, without blocking the bot
Before the changes, the main source of latency was the model having to call the search tool itself. I therefore had the bot search using the customer's message before calling the model, then insert the top results directly into the turn. The model usually gets the information it needs from the start without calling a tool, which is how the count dropped from 10 calls to 1.
The one requirement is that presearch must have a strict timeout. I set it to 1.5 seconds. If it takes longer or fails, I skip it and insert nothing. The model still has its own search tool as a fallback. The customer sees no difference except for that turn being a little slower.
PRESEARCH_TIMEOUT = 1.5   # วินาที

def presearch_block(user_text: str) -> str:
    try:
        r = requests.get(SEARCH_URL, params={"q": user_text, "limit": 5},
                         timeout=PRESEARCH_TIMEOUT)
        r.raise_for_status()
        return format_hits(r.json())      # ผลอันดับต้น ๆ เป็นข้อความสั้น ๆ
    except Exception:
        return ""                         # ช้าหรือล้ม ข้ามไป ห้ามให้บอทต้องรอ
How I check that the cache really is stable
What I watch most closely in this system is that it can fail silently. If the hash is calculated from data containing values that vary unintentionally (such as the current time or an unpredictable list order), the row will be rewritten every time, the version will change every time, and the prompt cache will be invalidated on every turn without a single visible error. I therefore have a short checklist that I run whenever I add a new Mapper.
- Call the hot endpoint twice in succession without changing anything. The ETag must be the same, and the second call must return 304.
- Open an item's admin page, click save without changing a single character, then call the endpoint again. The ETag must stay the same.
- Change one word in that item and save. The ETag must change, and only one row must change.
- Run the full backfill on unchanged data. It must write zero rows.
H1=$(curl -sI 'https://example.com/api/bot/knowledge?part=hot&locale=th' | grep -i '^etag')
php artisan knowledge:index            # ต้องไม่เขียนแถวไหนเลย
H2=$(curl -sI 'https://example.com/api/bot/knowledge?part=hot&locale=th' | grep -i '^etag')
[ "$H1" = "$H2" ] && echo "[OK] version นิ่ง" || echo "[ERR] version ขยับโดยไม่มีอะไรเปลี่ยน"
If the third check passes but the second fails, the Mapper contains a value that should not be in the assembled text. I go through the fields one by one to see which value varies. It is usually a timestamp or an order that hasn't been sorted. The fix is to remove that field or make the order deterministic before assembling the text. Another thing to know is that separating hot content from the rest does not happen intelligently on its own. I set the hot flag manually by content type and periodically inspect the output with --show=hot, because what customers frequently ask about changes over time. What used to be hot may no longer be hot, and something no one used to ask about may become this week's recurring question.
Lessons I carry over to other work
- Separate "must know every time" from "search when needed" using an explicit numerical character cap, not a gut feeling.
- Use hashes to control writes. Rows that haven't actually changed must stay untouched, or the prompt cache will be invalidated even though nobody edited anything.
- Have the endpoint return ETag and 304 so it can be called as often as needed without wasting a penny.
- presearch must have a strict timeout and fail silently, without blocking the bot.
- Always have a repeatable backfill pass, because events do not cover every path.
Do not use real customer conversations as examples or system seeds. I use entirely fictional examples, such as Product A costs X, because conversations are private information belonging to people who do not know they are being used as examples.
Summary
What I actually did comes down to this: don't include the whole site, and don't rely on search alone. Split the content into two groups with a cap, control writes with hashes, and have the bot search ahead with a timeout. My response time went from 10.5 seconds to 6.1 seconds, tool calls went from 10 to 1, and the prompt went from 110k to 77k tokens. But again, those results came from 8 test questions. For other sites with more or less content, the hot cap needs to be adjusted to the customer's budget and patience. If I've left anything out or the numbers don't line up with someone else's site, I'll come back and update this later.
Want us to set this up?
Get help with server setup, configuration, migration, or troubleshooting. Save time for the work that matters.
Hit something like this? Stuck somewhere?
Come trade notes on the LinuxThai board
Comments 0
No comments yet — be the first