WireGuard Stalls After an Endpoint IP Change; Keepalive Can't Help
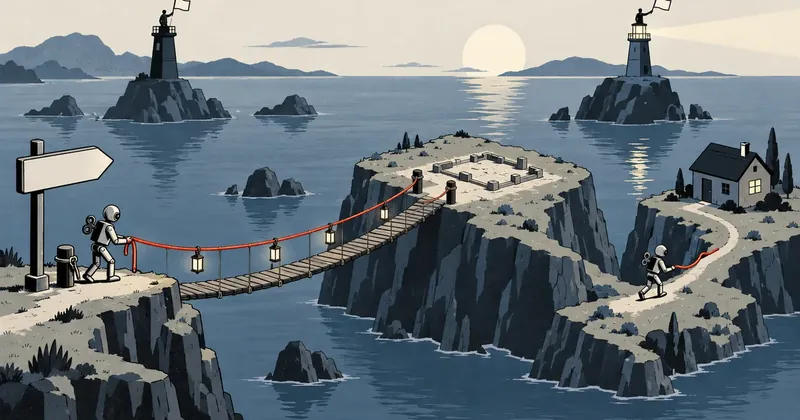
PersistentKeepalive does its job correctly every 25 seconds. The problem is that it sends to the IP remembered when the tunnel came up, which is no longer where the endpoint lives.
1-minute summary
- Symptom / problem
- A WireGuard tunnel with a DDNS name as Endpoint drops and does not recover after a power cut or an IP change
- Who should read
- People using WireGuard to reach home through a DDNS name
- Fix in short
- The client resolves the name only once at up. Fix it on the client side so it re-resolves, and make sure the DDNS updater is not a single point of failure.
A WireGuard tunnel I use to access one work site kept having the same problem: after a power outage at the site, or after the ISP changed its IP, the tunnel would disconnect and stay that way. It would never recover on its own, even long after the site's DDNS hostname pointed to the new IP. I had to manually click deactivate and then activate on the client every time, which meant an unattended client was stuck. I tried fixing the wrong thing twice before understanding which side the problem was on, so I am writing down both the mistakes and the fix.
The hostnames, IPs, ports, tunnel names, and public keys in this article are all examples. The timing thresholds, script structure, and symptoms are real. This article does not cover installation; that is in the full client guide.
The setup and the symptoms
The site has a single dynamic public IP and uses the hostname site.example.com, updated by ddclient. Inside, two WireGuard servers sit on the same LAN and back each other up. The primary runs Debian; the other is a Raspberry Pi. They listen on different ports and each has its own set of peers. Both perform NAT through their LAN interfaces. The server configs have no Endpoint lines for peers because the clients initiate the connections.
The main client runs Windows behind a mobile provider's CGNAT. Its config looks entirely normal.
[Interface]
PrivateKey = <CLIENT_PRIVATE_KEY>
Address = 10.10.10.2/32

[Peer]
PublicKey = <SERVER_PUBLIC_KEY>
AllowedIPs = 10.10.10.0/24, 192.168.10.0/24
Endpoint = site.example.com:51888
PersistentKeepalive = 25
Every time the site's IP changed, the client tunnel would disconnect and stay stuck. The latest handshake would get older and older, and the connection would not return until someone stopped and started the tunnel.
Two wrong guesses: NAT timeout and a server watchdog
My first guess was a NAT timeout because the client was behind CGNAT, where NAT entries expire quickly. I added PersistentKeepalive = 25. My own old notes even said, "The real fix is keepalive," which was wrong. Keepalive does fix NAT problems, but not this one. The symptoms stayed exactly the same.
On my second attempt, I built a server watchdog to check the handshake and restart the interface if it was too old. I thought waking the server up would let the client reconnect. That did not fix it either, and once I traced the packet path, I saw why it could never work. No matter how many times the server restarted, the client still would not know the new IP.
The actual cause is that WireGuard does not store the hostname in the tunnel at all. wg-quick on Linux or the tunnel service on Windows resolves the Endpoint name once when bringing the tunnel up, then passes the IP to the kernel to remember. After that, nothing queries DNS again. A peer's endpoint can change only when a correctly authenticated packet arrives from a new IP. That works for a server seeing a client move, but it does not work in reverse, because my server has no Endpoint for the client and never initiates traffic to it.
PersistentKeepalive keeps the NAT mapping open. It does not query DNS again. If the endpoint IP changes, it will keep sending to the old IP at regular intervals forever. Every config that uses a dynamic hostname in Endpoint needs a separate mechanism to resolve it again.
Using latest-handshakes as a health indicator
The only number that tells me whether the tunnel is actually alive is the time of the latest handshake. An Active status or transmit counter tells me nothing.
$ wg show wg0 latest-handshakes
<SERVER_PUBLIC_KEY>     1790000000

$ wg show wg0 endpoints
<SERVER_PUBLIC_KEY>     203.0.113.10:51888
The last column of latest-handshakes is an epoch timestamp. A value of 0 means there has never been a handshake since the interface came up. A working tunnel with keepalive performs a new handshake roughly every two minutes, so I treat anything older than 150 seconds as stuck. Meanwhile, endpoints shows the IP the kernel currently remembers, which I can compare directly with the DNS result.
To distinguish this problem from something else, I compare the results of three commands on the client. If the handshake is old and the IP returned by DNS differs from the endpoint remembered by the kernel, it is the problem described in this article. If the two match but the handshake is still old, the problem lies elsewhere, such as a port not being forwarded at the site or a server that is down. Resolving the name again will not help, no matter how many times I do it.
# เทียบสามค่าบนเครื่อง client
getent hosts site.example.com          # DNS ตอนนี้ตอบ IP อะไร
wg show wg0 endpoints                  # kernel จำ IP อะไรอยู่
hs=$(wg show wg0 latest-handshakes | awk '{print $2; exit}')
echo "handshake เก่า $(( $(date +%s) - hs )) วินาที"
To see the recovery mechanism work without waiting for an actual power outage, on Linux I can deliberately set the wrong endpoint with wg set wg0 peer '<SERVER_PUBLIC_KEY>' endpoint 203.0.113.10:51888, then check whether the next script run restores the IP returned by DNS and writes the expected log entry. This tests only the client half. The DDNS half needs a separate check, covered at the end of the article.
Fixing the Windows client: a scheduled task every 1 minute
The Windows client has no endpoint-changing command as convenient as Linux's. The most direct approach is to restart the tunnel service, forcing it to reread the config and resolve the name again. Each tunnel's service is named WireGuardTunnel$<ชื่ออุโมงค์>. The script I use is less than 25 lines long.
# wg-reresolve-win.ps1 : ถ้า handshake ค้างเกินเกณฑ์ ให้ restart บริการอุโมงค์
$ErrorActionPreference = 'SilentlyContinue'
$wg        = 'C:\Program Files\WireGuard\wg.exe'
$tunnel    = 'site-a'
$svc       = 'WireGuardTunnel$' + $tunnel
$threshold = 150
$log       = 'C:\ProgramData\wg-watchdog\wg-watchdog.log'

$s = Get-Service -Name $svc -ErrorAction SilentlyContinue
if (-not $s -or $s.Status -ne 'Running') { exit }       # คนปิดเองไว้ ไม่ยุ่ง

$line = & $wg show $tunnel latest-handshakes 2>$null | Select-Object -First 1
if (-not $line) { exit }
$hs = 0; [void][int]::TryParse((($line -split '\s+')[-1]), [ref]$hs)
if ($hs -le 0) { exit }                                  # ยังไม่เคย handshake ไม่ restart

$now = [int][double]::Parse((Get-Date -UFormat %s))
$age = $now - $hs
if ($age -gt $threshold) {
    "$(Get-Date -Format 'yyyy-MM-dd HH:mm:ss') handshake stale ${age}s -> restart $svc" |
        Out-File -Append -Encoding utf8 $log
    Restart-Service -Name $svc -Force
}
I deliberately included two early exit conditions. First, if the service is not Running, exit, because that means someone has stopped the tunnel and the watchdog should not start it for them. Second, if the handshake is 0, exit, because the machine may not have internet access yet. Repeatedly restarting while offline does not help.
The scheduled task must run as SYSTEM because restarting a service requires administrator privileges, and it needs to work even when nobody is logged in. The command to create it must run from an admin window.
schtasks /create /tn "wg-reresolve" /ru SYSTEM /sc minute /mo 1 /f `
  /tr "powershell.exe -NoProfile -ExecutionPolicy Bypass -File C:\ProgramData\wg-watchdog\wg-reresolve-win.ps1"
Fixing the Linux client: wg set endpoint without a restart
Linux offers a cleaner approach because wg set can change a peer's endpoint while the tunnel is up, without restarting it or interrupting other connections. This script runs roughly every 30 seconds on the client.
#!/bin/bash
# wg-reresolve-client.sh : resolve ชื่อ DDNS ซ้ำ แล้วอัปเดต endpoint ถ้า IP เปลี่ยน
IFACE=wg0
HOST=site.example.com
PORT=51888
PEER='<SERVER_PUBLIC_KEY>'

ip=$(getent hosts "$HOST" | awk '{print $1; exit}')
[ -z "$ip" ] && exit 0                     # DNS ตอบไม่ได้ อย่าแตะของเดิม
want="$ip:$PORT"
cur=$(wg show "$IFACE" endpoints 2>/dev/null | awk -v p="$PEER" '$1==p{print $2}')
if [ "$cur" != "$want" ]; then
  wg set "$IFACE" peer "$PEER" endpoint "$want" \
    && logger -t wg-reresolve "endpoint $cur -> $want"
fi

# handshake ค้างนานทั้งที่ endpoint ตรงแล้ว ให้ตั้งซ้ำอีกครั้งเพื่อกระตุ้น
hs=$(wg show "$IFACE" latest-handshakes 2>/dev/null | awk -v p="$PEER" '$1==p{print $2}')
now=$(date +%s)
if [ -n "$hs" ] && [ "$hs" -gt 0 ] && [ $((now-hs)) -gt 180 ]; then
  wg set "$IFACE" peer "$PEER" endpoint "$want"
fi
The line that exits immediately when DNS returns an empty result is essential. Without it, the script would set the endpoint to an empty value plus a port during a DNS outage, breaking an otherwise working tunnel.
Restart the tunnel service
Runs every 1 minute as SYSTEM and acts on a handshake older than 150 seconds. Restarting briefly interrupts connections through the tunnel, but guarantees that the name is resolved again.
wg set endpoint while running
Runs every 30 seconds and compares the DNS IP with the endpoint remembered by the kernel. If they differ, it changes only that value. The tunnel stays up, with another refresh when the handshake is older than 180 seconds.
The server watchdog is only a fallback
I kept the server watchdog from my second wrong guess, but made its role explicitly a fallback in case the server interface itself gets stuck after power returns. It loops every 15 seconds and runs as a service on both servers.
#!/bin/bash
# wg-watchdog.sh : restart wg0 ถ้า handshake ล่าสุดของทุก peer เก่าเกินเกณฑ์
IFACE=wg0
THRESHOLD=150      # วินาที
COOLDOWN=600       # ห่างจาก restart ครั้งก่อนอย่างน้อยเท่านี้
LOG=/var/log/wg-watchdog.log
last=0
while true; do
  now=$(date +%s)
  newest=0
  while read -r _pk hs; do
    if [ -n "$hs" ] && [ "$hs" -gt "$newest" ] 2>/dev/null; then newest=$hs; fi
  done < <(wg show "$IFACE" latest-handshakes 2>/dev/null)
  # newest เป็น 0 คือไม่มี client ต่ออยู่เลย ไม่ restart
  if [ "$newest" -eq 0 ]; then sleep 15; continue; fi
  age=$((now-newest))
  if [ "$age" -gt "$THRESHOLD" ] && [ $((now-last)) -gt "$COOLDOWN" ]; then
    echo "$(date '+%F %T') handshake stale ${age}s -> restart $IFACE" >> "$LOG"
    systemctl restart "wg-quick@${IFACE}"
    last=$now
  fi
  sleep 15
done
The server's 150-second threshold matches the client's, making it easy to compare logs from both sides. Their roles are clearly different, though. The client provides the fix; all the server can do is bring its own interface back to a clean state. If the client still does not know the new IP, the server will restart and then keep waiting. That is why it needs a cooldown; otherwise, it would restart on every iteration for as long as the client was absent.
Two safeguards keep it from hurting itself: if newest is 0, no client is connected, perhaps because everyone is on the LAN, so there is nothing to do; and a COOLDOWN of 600 seconds prevents frequent restarts when clients really are absent. I can access the servers directly over the LAN, so restarting WireGuard does not cut off my own ssh connection. Every service is enabled so it returns automatically when power comes back. For another perspective on separating causes before restarting anything on a machine, see Distinguishing a broken link from an ISP outage.
This site has no fixed IP, so DDNS is the only option. At a site with a static IP, I can put that IP directly in Endpoint. The problem in this article will not occur, and no client watchdog is needed.
The DDNS updater: avoid a single point of failure
Fixing the client still leaves the other half of the problem. If DDNS is not updated, the client will get the old IP no matter how many times it resolves the name. Originally, ddclient ran on just one small machine. When that machine went down or hung, the hostname stayed stuck on the old IP, and every service depending on it became unavailable at once.
I switched to running ddclient on two machines in parallel—the two servers themselves—with daemon=300 on both, updating two hosts in the same zone through the DNS provider's API. Running both causes no harm because each machine simply writes the current IP to the same records. Whichever writes first, the value is the same.
The config is stored at /etc/ddclient.conf, owned by root with permissions 600, and every change must be applied identically on both machines.
daemon=300
ssl=yes
use=web, web=https://checkip.amazonaws.com/
protocol=cloudflare
zone=example.com
login=token
password='<API_TOKEN>'
site.example.com,cam.example.com
While setting this up, I ran into three config pitfalls.
- The external IP checker was slow. I originally used
use=web, web=freedns, which took over 1000 ms to respond and sometimes stalled untilddclient -forcetimed out after more than 30 seconds. I switched to a service that returns the IP as plain text and measured around 252 ms. - For comment lines ending in a backslash, such as
#protocol=googledomains \, the newer ddclient version on one of the two machines read the next line as a continuation, producing the warningInvalid Value for keyword 'login' = ''. I had to delete the entire old comment block, rather than put # in front of only the first line. - A stale cache: if changing the config has no effect, delete the cache and force one run with output visible on screen.
# ล้าง cache แล้วบังคับอัปเดตหนึ่งรอบ ดูผลทันที
rm -f /var/cache/ddclient/ddclient.cache
ddclient -daemon=0 -verbose -force

# ตรวจสถานะประจำ
systemctl status ddclient --no-pager
grep -o 'status-ipv4=[a-z]*' /var/cache/ddclient/ddclient.cache
The value to look for in the cache is status-ipv4=good for every host.
The numbers and the checking sequence
This problem has two halves that need to be fixed together. First, the client needs a mechanism to resolve the name again because WireGuard does not do it. Second, the name being resolved needs to be updated by more than one machine. A server watchdog and keepalive are worth having, but they do not fix this problem. The 150-second threshold and 1-minute interval are the values I use at this site; use shorter or longer intervals as needed. If I have left anything out of the explanation or made a typo, I will come back and correct it later.
Hit something like this? Stuck somewhere?
Come trade notes on the LinuxThai board
Comments 0
No comments yet — be the first