#Crawler
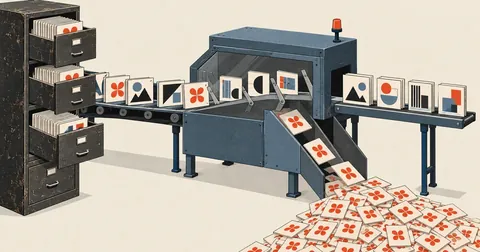
Migrating an Old .aspx Site to a JSON Catalog and Filtering Images
The owner of an old .aspx site asked me to rebuild it, but more than a decade of content was in a database I could no longer access. I collected the pages from the site itself to build a JSON catalog that preserved every legacy_id, then wrote a three-layer image filter to keep stray QR codes from becoming article covers.
My Firewall Permanently Banned Googlebot and Hid Sites from Search
I investigated why sites disappeared from search results and found Googlebot in my own firewall's permanent ban list. 408 of 500 entries came from the counter tallying WAF false positives. How I lifted the bans, wrote a script to fetch official bot IP ranges into the ignore list daily, and dealt with a grep trap and the side effects of blocking entire countries.
AI Crawler Overloads ?add-to-cart= — Block It Without Hurting SEO
Server load triggered an email alert. The logs showed that 84% of the day's traffic came from one AI crawler following add-to-cart links for every product. I added layers of protection with robots.txt, rel=nofollow and nginx limit_req while keeping all product pages indexable.
AdSense Says ads.txt Is Missing: Tracing the Logs Layer by Layer
The AdSense Sites page reports ads.txt as "Not found" even though the file exists and is correct — a forensic investigation using curl + access logs to prove, layer by layer, whether Googlebot visited and what it received. Case closed: nothing was blocking it; Google's own status was stale.