#Logging

Passing the Sandbox Doesn't Mean It Works — 7 False Signals
The automated ordering system I wrote passed every command in a provider's sandbox, but almost everything the sandbox told me differed from reality, from response times and charges to accepted names and items that were created successfully but could not be found. Here are 7 false signals and how to write code that does not fall for them.
Making 20,000+ API Calls That Resume Without Leaving Corrupt Files
Generating 26,850 files through an API limited to 20 calls per minute requires three pieces—a system-wide throttle, resuming from what is already on disk, and a separate file validator—because files interrupted by network failures still have the right extension and a nonzero size.
Cannot Delete Faces from a Terminal: API Returns notSupport
The door's face recognition terminal advertises a command to delete faces from FDLib, but every variation I tried returned notSupport. People who had left could still scan their faces and get in. This article covers the dead ends, the approach that actually worked using UserInfo/Modify with the smallest possible body, and the two-way user registry sync that runs every night.
Reads from a Replica Must Show How Many Minutes Old the Data Is
replication can report a lag of 0 seconds while the data is stuck at yesterday, because these two signals measure different things — how to set up a monitor that checks both Seconds_Behind_Master and business data freshness, catches anyone writing directly to the slave, and has another check watching the monitor itself
Secrets Set to 600, but 0644 Logs Go Offsite Every Night
The .env is encrypted and permissions are locked down on every secret file, but customer data still leaks off the machine every night through something nobody classifies as confidential: logs that every account on the machine can read, bundled into backups uploaded to object storage. Here is how I stop it at the source by logging only result codes.
The Service Is Running but Dead — systemd restart Cannot Help
A long network outage broke DNS. A daemon holding a session with an external API failed to log in 194 times, then hung halfway through the process. It never exited, so the system never restarted it — why I stopped checking whether a process was alive and started measuring data freshness instead.
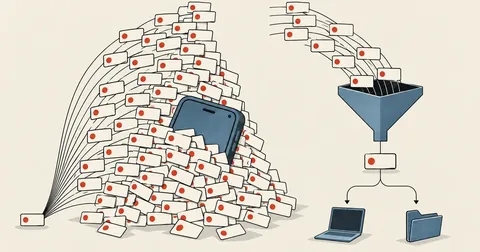
Too Many Alerts Mean No Alerts: Tuning a Bot People Will Read
In one day, 28 events became 56 messages, and 57 percent of all events were repeat alerts every 30 minutes. This article covers recipient tiers, merging overlapping cycles, state that survives restarts, and why you must not add keepalive to a chat app session.

Mailbox Compromised or Just Password Guessing? Prove It First
Telling a customer their account has been compromised is an allegation that needs decisive evidence first. This article covers what counts as decisive evidence, two cases with opposite outcomes, and the case I nearly reported incorrectly.
Sending Automated Job Files to Telegram and the Bot API's 50 MB Limit
Set up a small local service that takes files from scripts and sends them to me on Telegram, with outbound delivery only, no polling, and no incoming commands, along with the actual Bot API limits to know before writing it, including 50 MB per file, images over 10 MB that must be sent as documents, and the Thai text trap in curl on Windows.
A 25-Hour Power Outage Left Scheduled Jobs Missing
The machine running my automated jobs lost power three times in three days, with the longest outage lasting 25 hours. When it came back, I found that jobs scheduled directly through Task Scheduler had skipped their runs entirely, while jobs managed by a dispatcher that checked the time itself had all caught up. This article covers the setting to enable, what to avoid during recovery, and the traps that led me to misread the status.
Tell a Broken Link from an ISP Outage Before Restarting Anything
A typical watchdog restarts NetworkManager when ping fails, which is wrong half the time because no internet access may mean the ISP is down, not that the adapter has failed. This article distinguishes three states using nmcli, then escalates from gentle recovery to PCI remove and rescan without rebooting the machine.
Every Layer Reported Success While the Output Was Garbage
In one day, four layers of the same automated pipeline failed together, but every layer reported success without a single error line. The person who caught it was a user who said the site was not updating. These are the rules I wrote afterward so that failing stages could speak up for themselves.
WordPress 500s, Empty debug.log — The Fatal Is in the Apache Log
WordPress returns 500 only on portfolio pages, but debug.log is empty — because the fatal error during theme rendering happens before WP logging is ready. The answer is in the apache error log (proxy_fcgi), along with a fix for a child theme with a stale template copied from an older parent version.
AdSense Says ads.txt Is Missing: Tracing the Logs Layer by Layer
The AdSense Sites page reports ads.txt as "Not found" even though the file exists and is correct — a forensic investigation using curl + access logs to prove, layer by layer, whether Googlebot visited and what it received. Case closed: nothing was blocking it; Google's own status was stale.

Reading exim mainlog for Stuck Clients — Mail Forensics Part 1
How I read /var/log/exim/mainlog to distinguish an office machine using the wrong password from an attacker running a brute force attack, with the commands I use when customers need answers fast.
Tracing Dovecot IMAP/POP Failures on DirectAdmin and Keeping 90-Day Logs
A follow-up to Mail Forensics — trace IMAP/POP failures in /var/log/mail.log on DirectAdmin, distinguish stuck clients from attackers using cross-protocol ratios, and adjust logrotate to keep a full 90 days of logs instead of defaults that lose them within days